Claude’s new auto eval tool – Hamel’s Blog
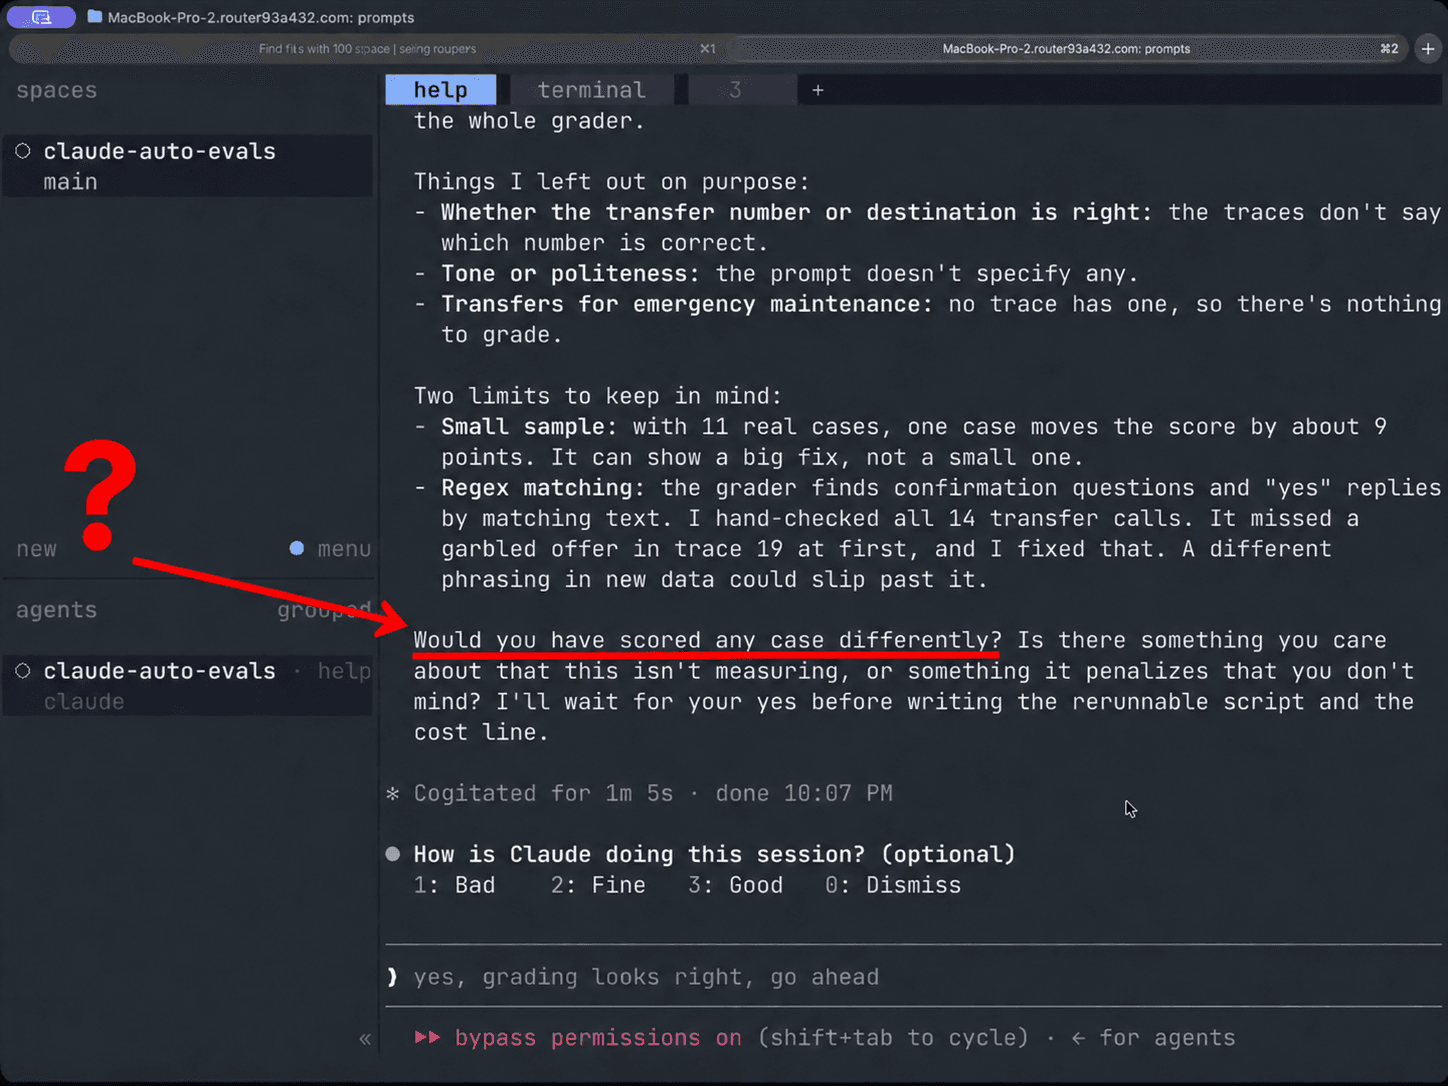
Reflections on trying Anthropic’s new eval plugin for Claude.
AI Engineers, Machine Learning Researchers, and Data Scientists
LLM evaluation involves testing model performance through multiple approaches including **multiple-choice benchmarks** (like MMLU), **verification methods** that check free-form answers against reference data, **LLM-based judges** that score responses using rubrics, and **leaderboard comparisons** based on human preferences.
Common metrics include overlap-based measures like BLEU and ROUGE, semantic similarity scores, and binary or Likert-scale categorizations to assess accuracy, relevance, and output quality. Evaluation strategies range from benchmark-based methods that provide quantifiable accuracy metrics to judgment-based approaches that assess broader qualities like response style and appropriateness.