


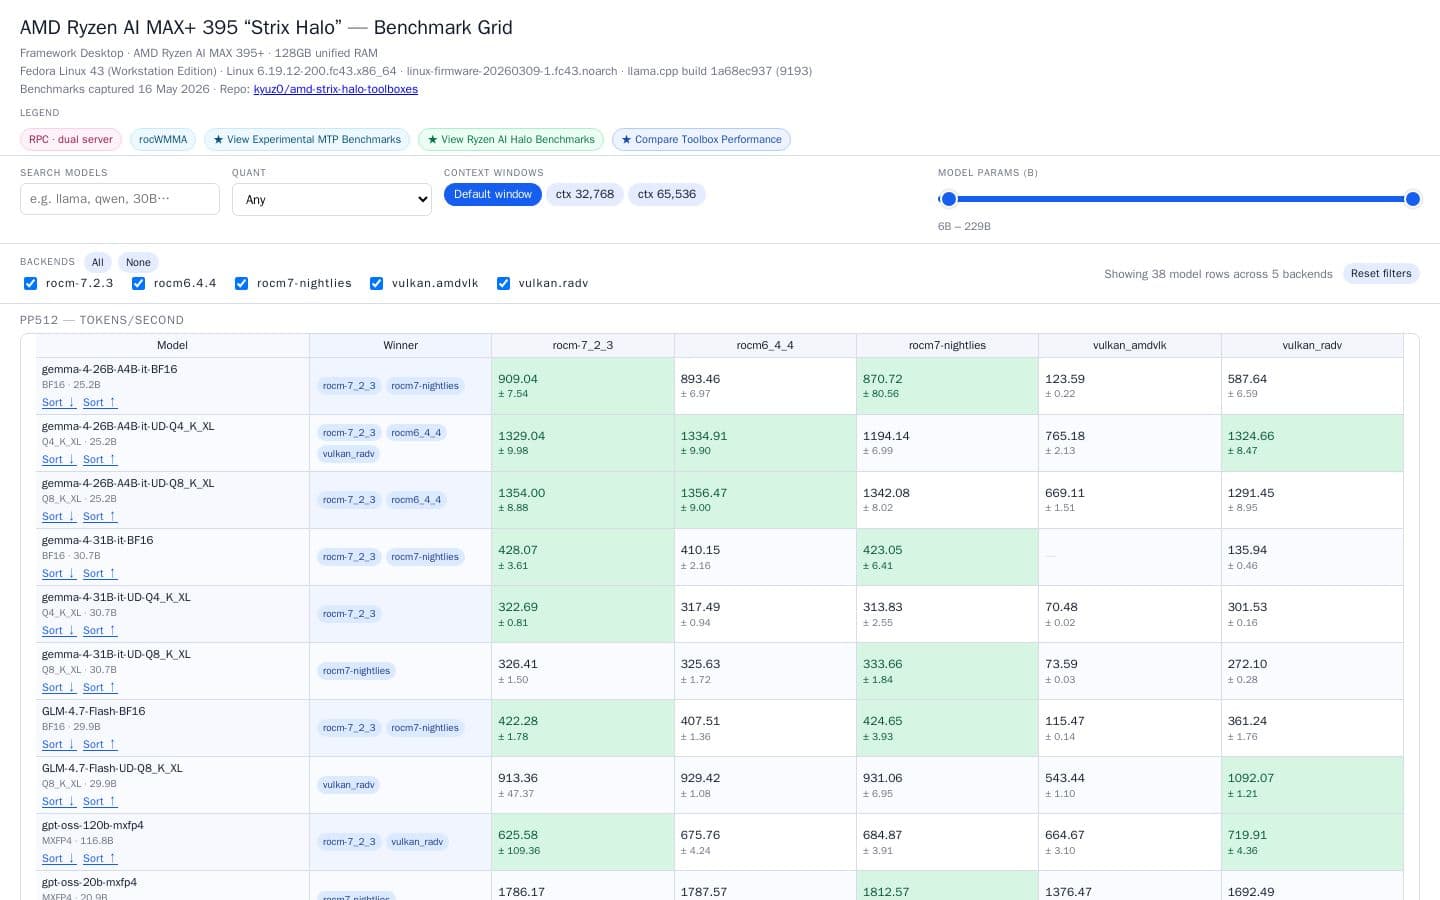
AMD Strix Halo — Backend Benchmarks (Grid View)
Backend benchmarks for AMD Strix Halo measuring tokens-per-second throughput across 17 LLM configurations ranging from 6.7B to 228.7B parameters. Test...
AI Engineers and Hardware Enthusiasts
Backend benchmarks for AMD Strix Halo measuring tokens-per-second throughput across 17 LLM configurations ranging from 6.7B to 228.7B parameters. Test...

In this video, I show how to run large language models like Qwen3-235B in Q3_K_XL and GLM 4.5-Air-106B in Q6_K_XL on any AMD Ryzen AI MAX “Strix Halo”...

Qwen 3.8 27B ROCmFP4 on AMD Strix Halo (Ryzen AI Max+ 395). Up to 36 tok/s via MTP Speculation, TurboQuant & Mesa RADV Wave64. - julianmb/q38rocm