hipfire-models/qwen3.8-27b · Hugging Face
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
This curated guide brings together 19 vetted LLM Inference resources, including 18 with structured technical analysis and 0 with practitioner field notes. Primary focus areas include LLM Inference Tool, AI Infrastructure Platform, C/C++ Library, Deployment Recipe, Engineering Experience Report. Primary sources include github.com, huggingface.co, fireworks.ai, kyuz0.github.io, linkedin.com.
| Resource | Category & Format | Key Takeaway & Notes |
|---|
| GitHub - warpfront/hipfire: RDNA-native LLM inference engine in Rust.github.com | GPU Inference Framework / open-source software project / open source on GitHub; weights on Hugging Face | Rust + HIP with no Python in the hot path; Ollama-style CLI and OpenAI-compatible API on loopback port 11435 |
|---|---|---|
| GitHub - MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark: Qwen3.8-Flash-Next on ONE DGX Spark (TP=1)github.com | Machine Learning Deployment Guide / Technical Documentation / open source | Enables serving a large 99 GiB vision-language model (text, image, video) on a single DGX Spark's 121 GiB unified memory. |
| harshatheg/Qwen-2.5-1B-RLCD · Hugging Facehuggingface.co | ML Inference Engine / open-source project with documentation and live demo / open source on Hugging Face | KV-cache broadcasting enables all schema fields to be evaluated in a single parallel pass instead of sequential token-by-token generation |
| GitHub - bilikaz/qwen38-flash-next-recipe: qwen38-flash-next recipe for solo GB10github.com | Deployment Recipe / Open source repository / Open source | Optimized for single NVIDIA DGX Spark (GB10) with 119 GB unified memory |
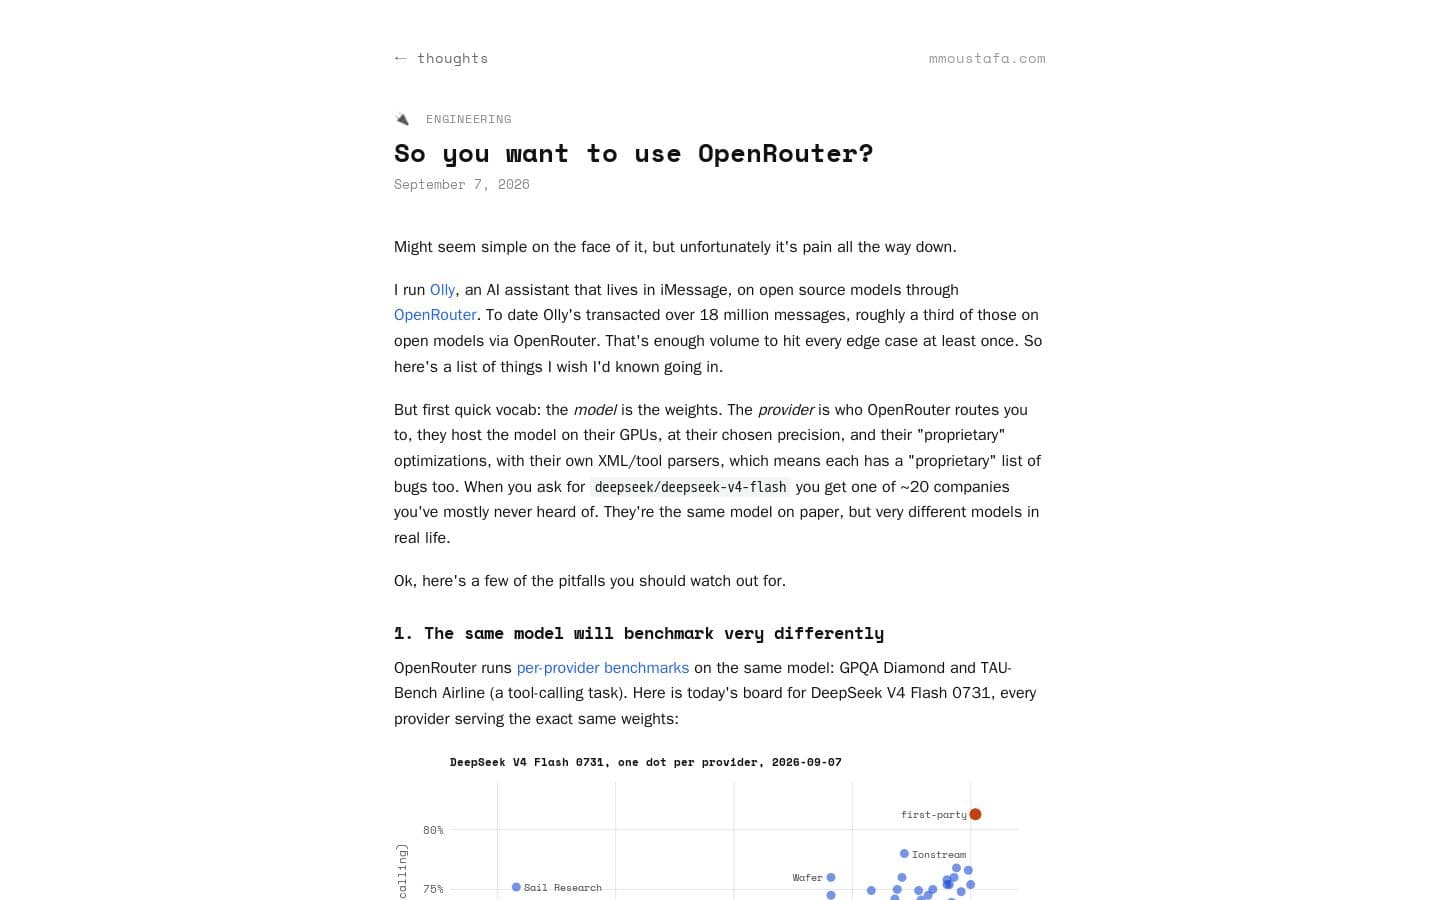
| So you want to use OpenRouter? — Mo Moustafammoustafa.com | Engineering Experience Report / long-form blog post / free online | The same model weights show up to 20-point benchmark swings across providers (e.g., GPQA Diamond ranges from 70.5% to 90.2% for DeepSeek V4 Flash) |
| Optimizing On-Device Inference for Apple Siliconperplexity.ai | ML Inference Engineering / technical blog post / free online | Rust runtime with custom Metal kernels eliminates PyTorch and MLX from the execution path entirely |
| GitHub - quimmedes/cafe-llama.cpp: A experimental fork of llama.cpp with LLM inference in C/C++github.com | LLM Inference Tool / Open source GitHub repository with documentation / Open source, free on GitHub | Provides flags to offload MoE expert weights to pinned host RAM (zero-copy DMA) or CPU RAM while keeping attention and KV cache on GPU |
| GitHub - LaurentZuijdwijk/llama.cpp: llama.cpp with adaptive speculative decoding (--spec-draft-adaptive) and a Vulkan backend tuned for AMD Strix Halo. 4.7x on structured output, 1.9x mainline prefill on MoE.github.com | Machine Learning Software / Open source repository / Open source | Implements adaptive speculative decoding that adjusts draft length based on measured acceptance rates rather than a fixed value. |
| feat(qwen4_exp): support Qwen3.8-Flash-Next by jason-fxz · Pull Request #257 · FlashML-org/FreeTokengithub.com | LLM Inference Engine PR / GitHub Pull Request / open source | Hybrid architecture: 36 gated delta net layers + 12 compressed block-sparse attention layers on 4 hyper-connection residual streams |
| The V100 Homelab Field Guide - a Hugging Face Space by KyleHessling1huggingface.co | Technical Hardware Guide / interactive tool / free online | Optimization techniques for Tesla V100 32GB GPUs |
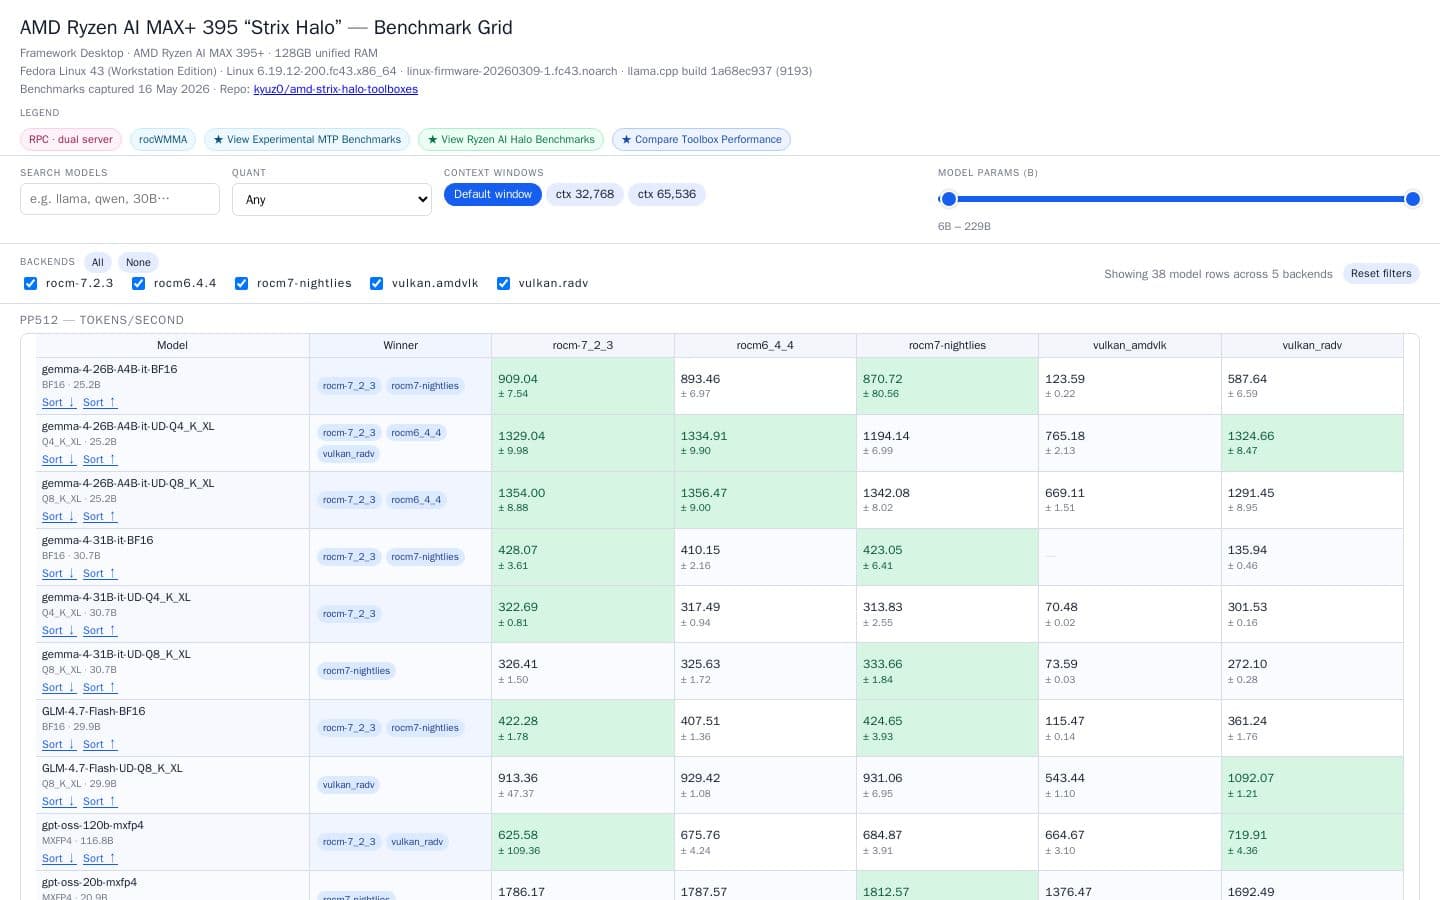
| AMD Strix Halo — Backend Benchmarks (Grid View)kyuz0.github.io | Performance Benchmarks / interactive benchmark dashboard / free online | Compares throughput (tokens-per-second) across 17 LLM configurations ranging from 6.7B to 228.7B parameters. |
| froggeric/Qwen-Fixed-Chat-Templates · Hugging Facehuggingface.co | LLM Inference Tool / open source repository / free, open source on Hugging Face | Fixes KV cache invalidation, empty think poisoning, and fatal agentic stalling in official Qwen templates |
| z-lab/Qwen3.6-27B-DFlash · Hugging Facehuggingface.co | Machine Learning Model / model repository / open source | Introduces DFlash, a speculative decoding method using block diffusion for drafting. |
| Fireworks AI - Fastest Inference for Generative AIfireworks.ai | AI Infrastructure Platform / cloud service / cloud subscription | Blazing-fast inference for open-source LLMs and image models. |
| GitHub - QuinsZouls/llama-cpp-turboquant at llama-nextgithub.com | Open Source Library / software repository / open source | Zero-dependency plain C/C++ implementation ensuring broad compatibility. |
A collection of bookmarks filtered by the tag "LLM Inference".
Showing 1-19 of 19 bookmarks tagged with "LLM Inference"
All Stories
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
High-performance Lemonade alternative for AMD Strix Halo & Radeon — latest MoE models (Ling-3.0-Flash, Qwen 3.8 Flash Next, Ornith 1.5), bleeding-...