The article explains the Lottery Ticket Hypothesis, showing that large neural networks contain small subnetworks that match full model performance. This challenges traditional bias-variance theory by proving overparameterization aids generalization rather than causing overfitting.
Highlights
Large neural networks contain small, trainable subnetworks called winning tickets.
This hypothesis contradicts the traditional bias-variance tradeoff principle.
Overparameterization increases the odds of finding effective solutions.
Massive models achieve high generalization despite theoretical predictions of failure.
The discovery marks a paradigm shift in understanding machine learning scaling.
A fast-paced whiteboard animation series unraveling Deep Learning and Large Language Models. Dive into core concepts, from Neural Networks basics to t...
rohanbansal.com
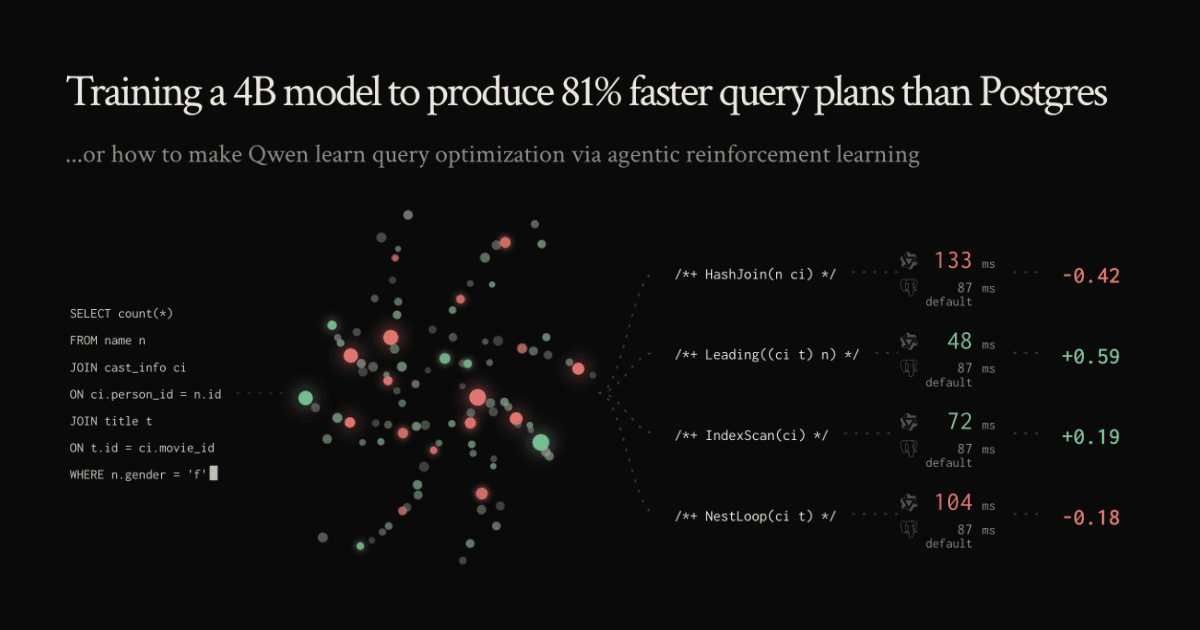
Training a 4B model to produce 81% faster query plans than Postgres
...or how to make Qwen learn query optimization via agentic reinforcement learning
gwern.net
LLM Daydreaming
Proposal & discussion of how default mode networks for LLMs are an example of missing capabilities for search and novelty in contemporary AI systems.