Fixing Tool-Call Accuracy in vLLM
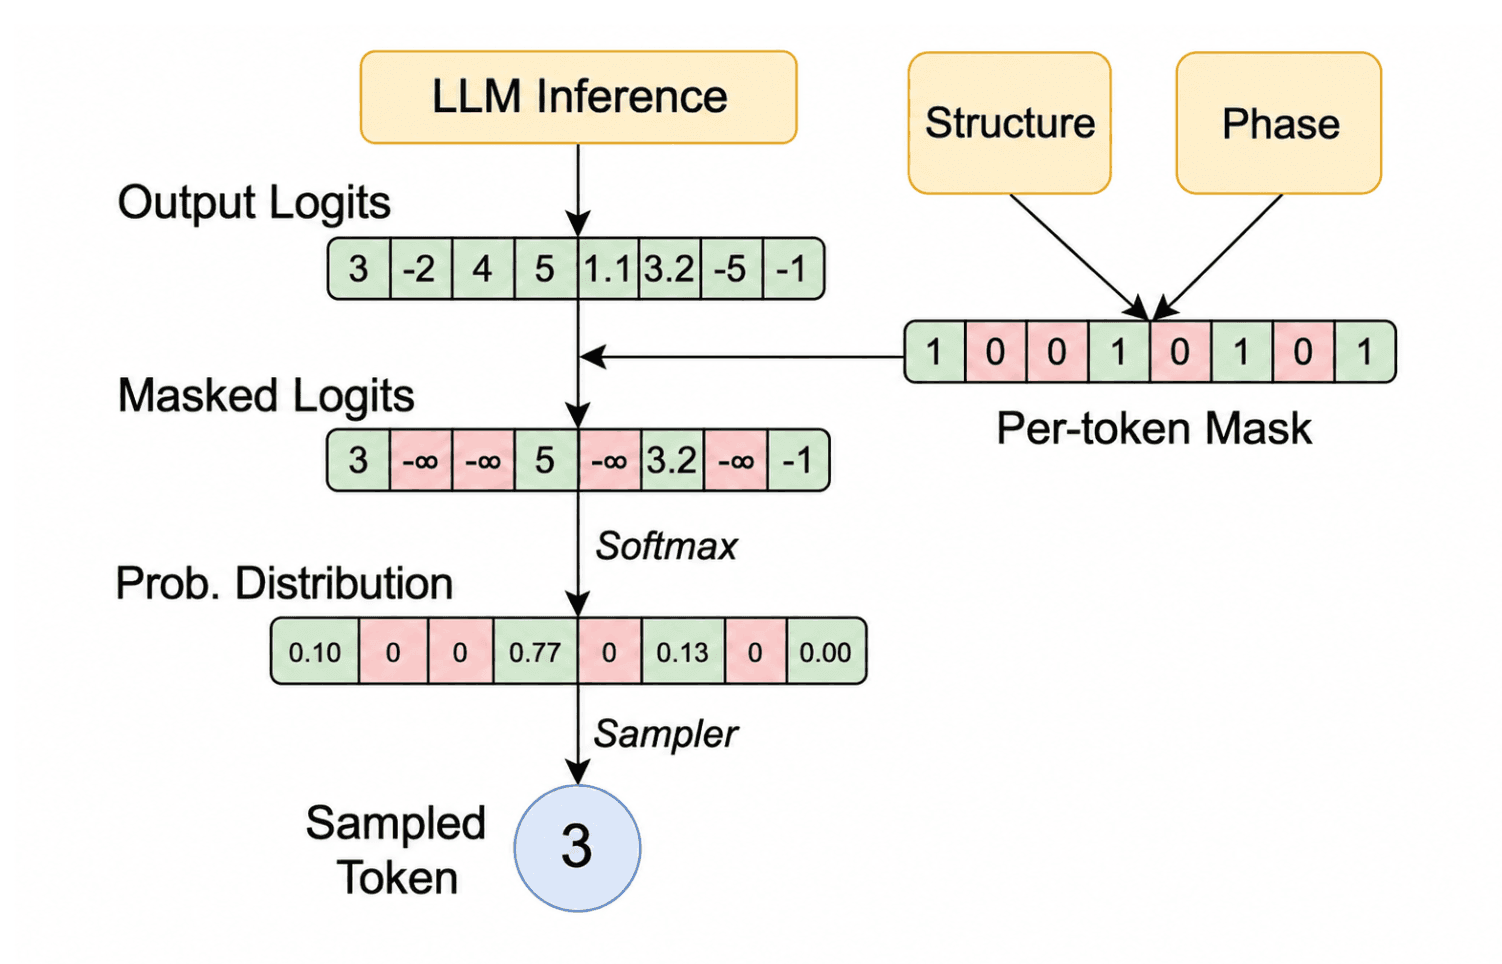
Tool call accuracy is an important part of serving open-weight AI models. When your tool calls aren’t accurate, the model builds up on nonsensical con...
ML engineers and LLM practitioners working on Apple Silicon who need low-latency structured output generation for production pipelines such as classification, routing, or extraction tasks
An MLX-based inference engine for Apple Silicon that evaluates multi-field JSON schemas in parallel via KV-cache broadcasting, achieving 5.6x to 7.0x latency reduction over autoregressive decoding with 100% schema validity.
Supports structured extraction, decision routing, and categorical classification with up to 255 enum choices per field and calibrated confidence scores. Includes a Python SDK, M4 Max performance benchmarks, and a live web visualizer for side-by-side comparison.
Tool call accuracy is an important part of serving open-weight AI models. When your tool calls aren’t accurate, the model builds up on nonsensical con...
Python command-line tool for interacting with AI models through the OpenRouter API/Cloudflare AI Gateway, or local self-hosted Ollama. Optionally supp...