Tool calling, open source, and the M×N problem
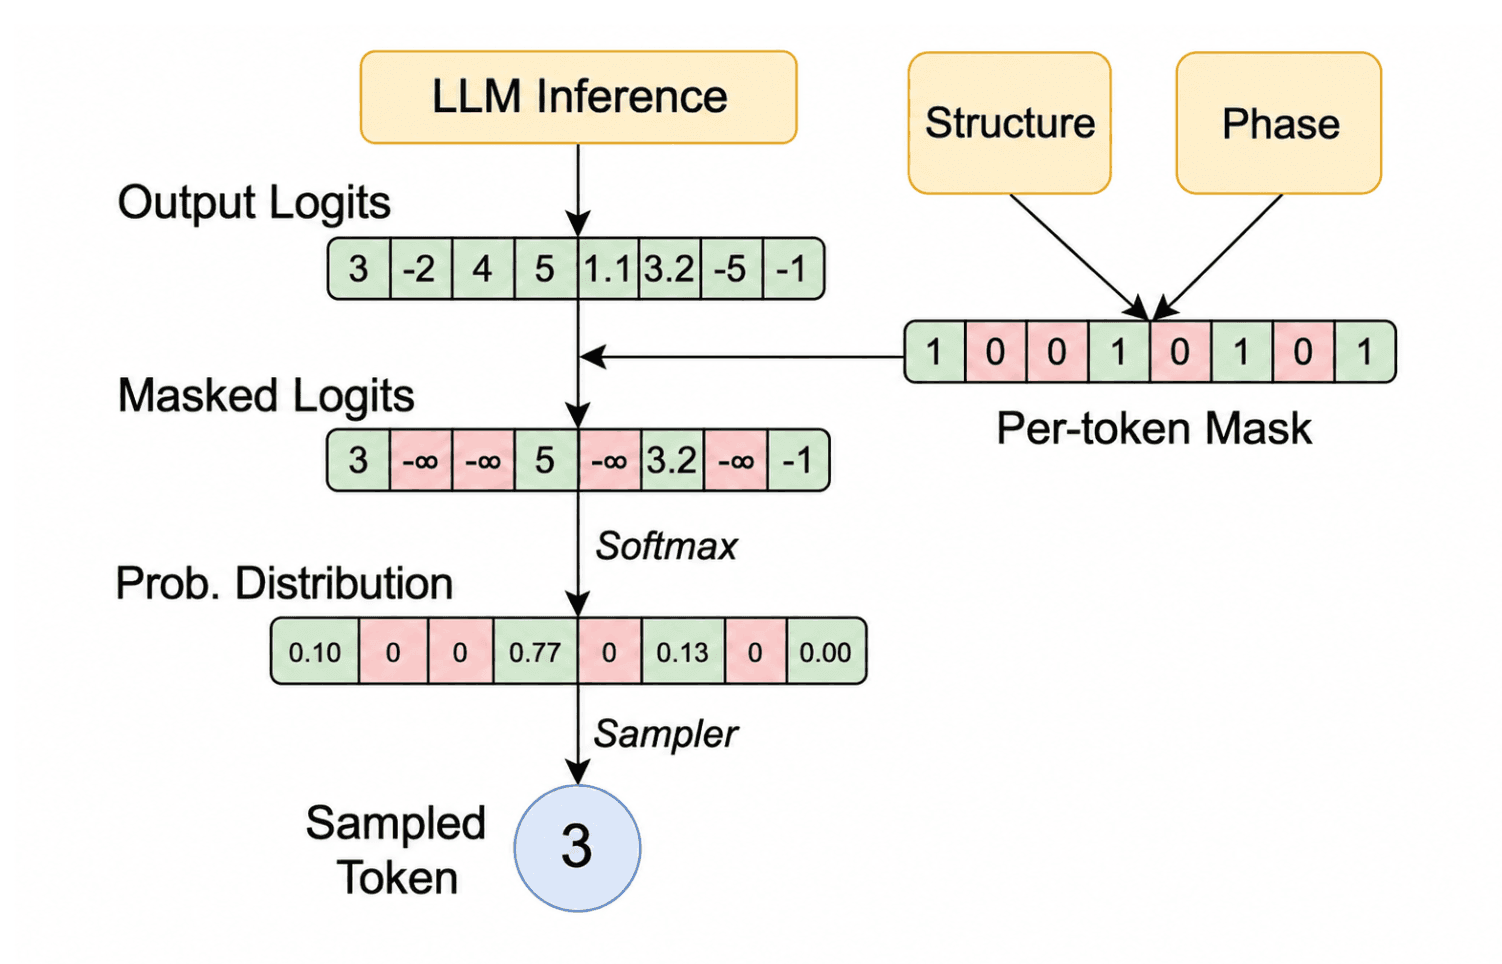
Tool calling with closed-source models is seamless. You pass a list of functions to the API, the model calls them, you get structured JSON back.
This curated guide brings together 13 vetted vLLM resources, including 12 with structured technical analysis and 0 with practitioner field notes. Primary focus areas include Machine Learning Model, AI Benchmark, AI Inference Engineering, Deployment Recipe, Developer Tool. Primary sources include github.com, huggingface.co, localmaxxing.com, recipes.vllm.ai, ubicloud.com.
| Resource | Category & Format | Key Takeaway & Notes |
|---|
| Fixing Tool-Call Accuracy in vLLMubicloud.com | AI Inference Engineering / technical blog post / free online | vLLM 0.31 added constrained decoding as a server-side flag, enabling guaranteed schema adherence for tool calls |
|---|
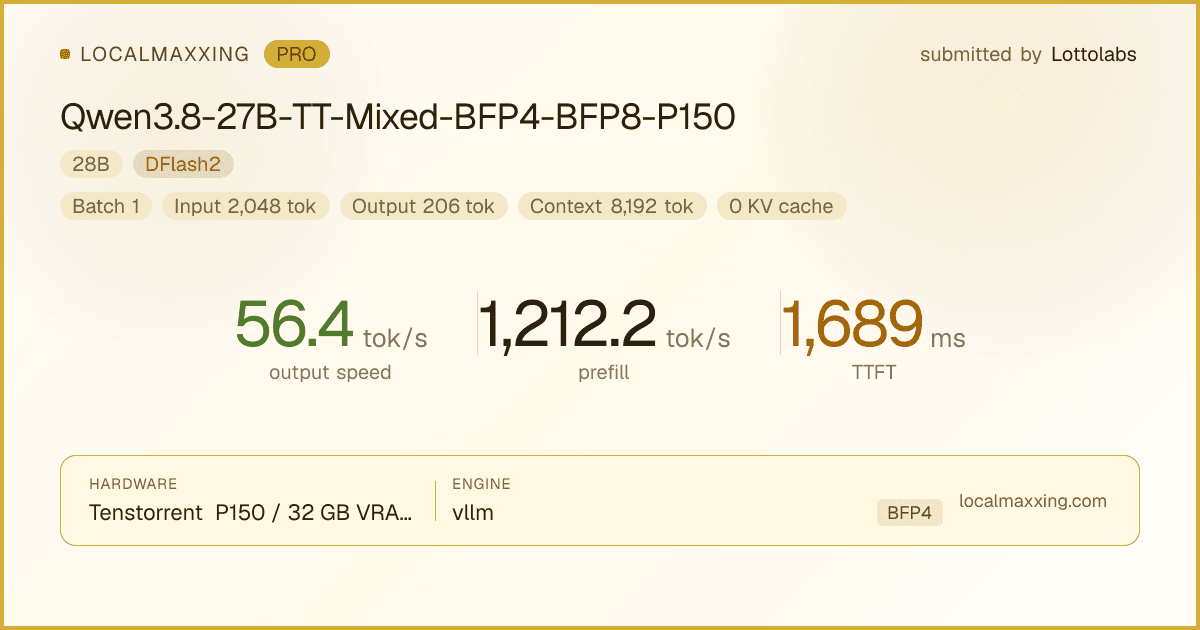
| Qwen3.8-27B-TT-Mixed-BFP4-BFP8-P150 — 56.4 tok/s on Tenstorrent P150 · 32 GBlocalmaxxing.com | AI Benchmark / benchmark result page / free online, sign-in required for full site | 56.4 tok/s output speed on a single Tenstorrent P150 32GB card with vLLM and BFP4/BFP8 mixed-precision quantization |
|---|
| GitHub - MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark: Qwen3.8-Flash-Next on ONE DGX Spark (TP=1)github.com | Machine Learning Deployment Guide / Technical Documentation / open source | Enables serving a large 99 GiB vision-language model (text, image, video) on a single DGX Spark's 121 GiB unified memory. |
|---|
| GitHub - bilikaz/qwen38-flash-next-recipe: qwen38-flash-next recipe for solo GB10github.com | Deployment Recipe / Open source repository / Open source | Optimized for single NVIDIA DGX Spark (GB10) with 119 GB unified memory |
|---|
| GitHub - MiaAI-Lab/Qwen3.8-27B-DGX-Spark-RTX-6000: Qwen3.8 27B for DGX Spark / RTX 6000 PROgithub.com | LLM Deployment Scripts / GitHub repository with shell scripts / Open source on GitHub | NVFP4 4-bit quantization with FP8 KV cache for ~2x KV memory savings |
|---|
| RedHatAI/Qwen3.6-35B-A3B-speculator.dspark · Hugging Facehuggingface.co | Machine Learning Model / Model Repository / Open source | Utilizes DSpark architecture which extends DFlash with a Markov head and a confidence head for improved token dependency and acceptance prediction. |
|---|
| z-lab/Qwen3.6-27B-DFlash · Hugging Facehuggingface.co | Machine Learning Model / model repository / open source | Introduces DFlash, a speculative decoding method using block diffusion for drafting. |
|---|
| RedHatAI/gemma-4-31B-it-NVFP4 · Hugging Facehuggingface.co | Quantized LLM Model / Model card / technical documentation / Free download from Hugging Face | FP4 quantization (group_size=16) reduces bits per parameter from 16 to 4, cutting disk and GPU memory by approximately 75% |
|---|
| amd-strix-halo-vllm-toolboxes/rdma_cluster/setup_guide.md at main · kyuz0/amd-strix-halo-vllm-toolboxesgithub.com | Technical Setup Guide / Documentation / Open Source | Configures a two-node AMD Strix Halo cluster for distributed vLLM inference with Tensor Parallelism over RoCE v2 |
|---|
| JetBrains/Mellum2-12B-A2.5B-Thinking — 12B / 2.5B active · MOE · 128K ctxrecipes.vllm.ai | Machine Learning Model / technical guide / open source | Supports a 131,072-token context window using a hybrid of sliding-window and full-attention layers. |
|---|
| GitHub - noonghunna/club-3090: Community recipes for serving LLMs on RTX 3090. Multi-engine (vLLM, llama.cpp, SGLang) and model-agnostic. Currently shipping Qwen3.6-27B configs for 1× and 2× cards.github.com | Open Source Software / open source repository / open source | Multi-engine support for vLLM, llama.cpp, and SGLang. |
|---|
| GitHub - Chen-zexi/vllm-cli: A command-line interface tool for serving LLM using vLLM.github.com | Developer Tool / open-source CLI tool / open source, free via pip install | Dual-mode interface: interactive terminal with menu navigation and direct CLI commands for automation |
|---|
| GitHub - MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks: GLM-5.3 Flash EXL3 for 2x DGX Sparksgithub.com | Reference | vLLM serving recipe for GLM-5.3-Flash using EXL3/TR3 4-bpw quantization (~164 GiB) on 2x NVIDIA GB10 with tensor-parallel size 2 over CX7. Serves an OpenAI-compatible API on port… |
|---|
A collection of bookmarks filtered by the tag "vLLM".
Showing 1-13 of 13 bookmarks tagged with "vLLM"
All Stories
Tool calling with closed-source models is seamless. You pass a list of functions to the API, the model calls them, you get structured JSON back.