

Terminal-Bench
A benchmark for terminal agents
AI researchers, machine learning engineers, and data scientists interested in novel LLM evaluation methods or domain‑specific language understanding
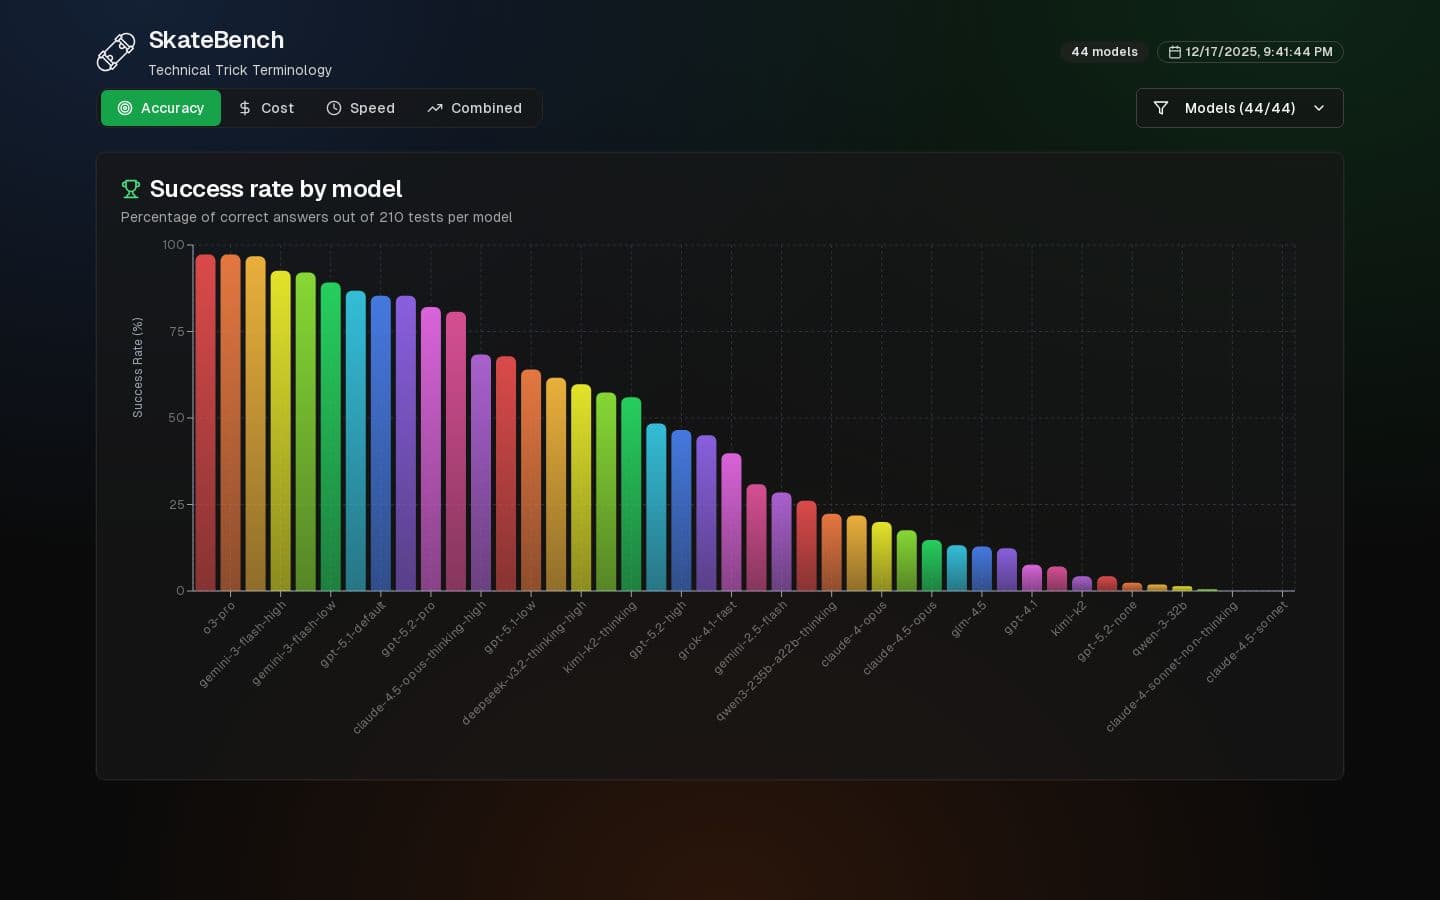
**SkateBench ranks 44 large language models on their ability to name skateboarding tricks correctly out of 210 tests.** Top performers include o3-pro, Gemini-3-Flash-High, and GPT-5.1-Default, with success rates visualized from 0% to 100%.
Leaderboard Comparing LLM Performance at Producing Hallucinations when Summarizing Short Documents - vectara/hallucination-leaderboard
Community recipes for serving LLMs on RTX 3090. Multi-engine (vLLM, llama.cpp, SGLang) and model-agnostic. Currently shipping Qwen3.6-27B configs for ...