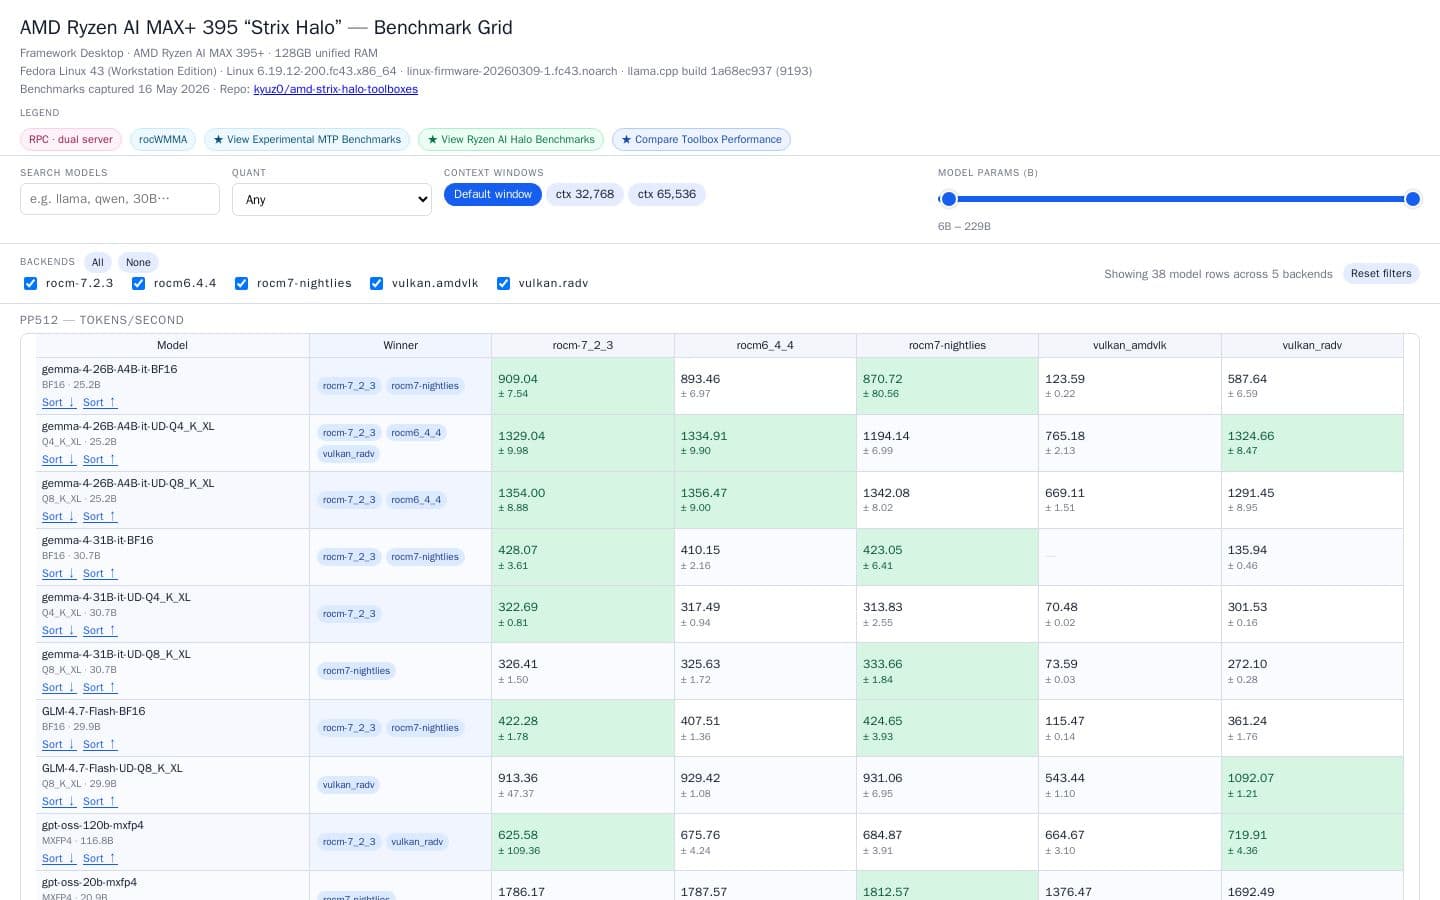
This content provides detailed performance benchmarks for various Large Language Models (LLMs) running on AMD Strix Halo hardware. It measures throughput in tokens per second across multiple software backends, including different ROCm versions and Vulkan, while testing various quantization methods.
Highlights
Compares throughput (tokens-per-second) across 17 LLM configurations ranging from 6.7B to 228.7B parameters.
Evaluates performance across multiple backends: rocm-7_2_3, rocm7-nightlies, rocm6_4_4, and vulkan_radv.
Analyzes the impact of different quantization levels, from BF16 to Q3_K_S, on inference speed.
Includes testing for a wide array of models such as Gemma 4, Llama 2, GLM-4.7, and Qwen 3.5/3.6.
Provides statistical error margins for each benchmarked throughput value.
auto-generated
Context
Audience
Machine Learning Engineers, Hardware Developers, and AI Researchers