hipfire-models/qwen3.8-27b · Hugging Face
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
This curated guide brings together 16 vetted Speculative Decoding resources, including 15 with structured technical analysis and 0 with practitioner field notes. Primary focus areas include Machine Learning Model, AI Benchmark, AI Model, AI Model Release, Deployment Recipe. Primary sources include github.com, huggingface.co, localmaxxing.com, research.meta.ai.
| Resource | Category & Format | Key Takeaway & Notes |
|---|---|---|
| GPU Inference Framework / open-source software project / open source on GitHub; weights on Hugging Face |
| Rust + HIP with no Python in the hot path; Ollama-style CLI and OpenAI-compatible API on loopback port 11435 |
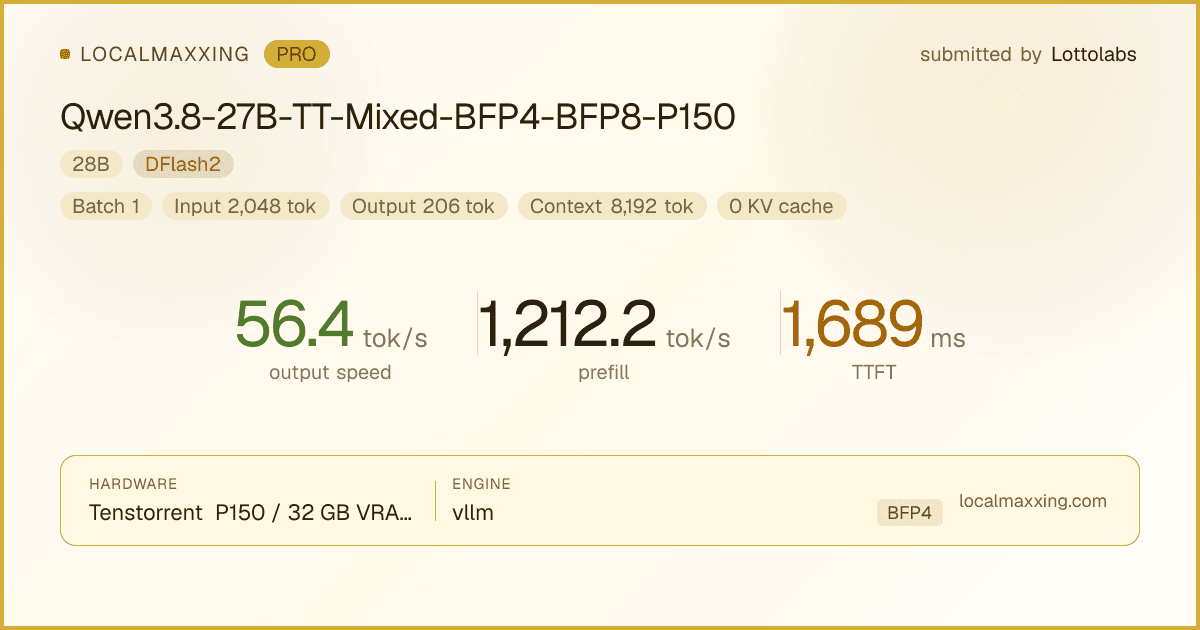
| Qwen3.8-27B-TT-Mixed-BFP4-BFP8-P150 — 56.4 tok/s on Tenstorrent P150 · 32 GBlocalmaxxing.com | AI Benchmark / benchmark result page / free online, sign-in required for full site | 56.4 tok/s output speed on a single Tenstorrent P150 32GB card with vLLM and BFP4/BFP8 mixed-precision quantization |
|---|
| GitHub - bilikaz/qwen38-flash-next-recipe: qwen38-flash-next recipe for solo GB10github.com | Deployment Recipe / Open source repository / Open source | Optimized for single NVIDIA DGX Spark (GB10) with 119 GB unified memory |
|---|
| GitHub - sxuff/qwen38-27b-nvfp4-dflash2-dgx-spark: Pinned stock Qwen3.8-27B NVFP4 + DFlash2 recipe and measured evidence for one NVIDIA DGX Sparkgithub.com | LLM Inference Recipe / open-source repository / open source | 71.50 tok/s median whole-request throughput across 27 frozen payloads, a 25.19% increase over the historical BF16 DFlash2 recipe at D=8 |
|---|
| GitHub - quimmedes/cafe-llama.cpp: A experimental fork of llama.cpp with LLM inference in C/C++github.com | LLM Inference Tool / Open source GitHub repository with documentation / Open source, free on GitHub | Provides flags to offload MoE expert weights to pinned host RAM (zero-copy DMA) or CPU RAM while keeping attention and KV cache on GPU |
|---|
| GitHub - LaurentZuijdwijk/llama.cpp: llama.cpp with adaptive speculative decoding (--spec-draft-adaptive) and a Vulkan backend tuned for AMD Strix Halo. 4.7x on structured output, 1.9x mainline prefill on MoE.github.com | Machine Learning Software / Open source repository / Open source | Implements adaptive speculative decoding that adjusts draft length based on measured acceptance rates rather than a fixed value. |
|---|
| GitHub - sxuff/qwen38-27b-nvfp4-dflash2-dgx-spark: Pinned stock Qwen3.8-27B NVFP4 + DFlash2 recipe and measured evidence for one NVIDIA DGX Sparkgithub.com | ML Inference Recipe / open-source repository with benchmark evidence / open source on GitHub | 4.63x median speedup: 57.11 tok/s (DFlash2) vs 12.34 tok/s (no-spec) on 27 paired requests |
|---|
| GitHub - julianmb/q38rocm: Qwen 3.8 27B ROCmFP4 on AMD Strix Halo (Ryzen AI Max+ 395). Up to 36 tok/s via MTP Speculation, TurboQuant & Mesa RADV Wave64.github.com | Machine Learning Deployment / Open source software repository / Open source | Achieves high throughput of up to 36 tokens per second |
|---|
| GitHub - MiaAI-Lab/Qwen3.8-27B-DGX-Spark-RTX-6000: Qwen3.8 27B for DGX Spark / RTX 6000 PROgithub.com | LLM Deployment Scripts / GitHub repository with shell scripts / Open source on GitHub | NVFP4 4-bit quantization with FP8 KV cache for ~2x KV memory savings |
|---|
| Introducing Muse Glimmer: An Open Agentic Model That Runs on Your Deviceresearch.meta.ai | AI Model Release / long-form article / open source | Optimized for always-on local workflows on Mac or PC with a single consumer GPU |
|---|
| RedHatAI/Qwen3.6-35B-A3B-speculator.dspark · Hugging Facehuggingface.co | Machine Learning Model / Model Repository / Open source | Utilizes DSpark architecture which extends DFlash with a Markov head and a confidence head for improved token dependency and acceptance prediction. |
|---|
| z-lab/Qwen3.6-27B-DFlash · Hugging Facehuggingface.co | Machine Learning Model / model repository / open source | Introduces DFlash, a speculative decoding method using block diffusion for drafting. |
|---|
| unsloth/gemma-4-26B-A4B-it-qat-GGUF · Hugging Facehuggingface.co | LLM Model Repository / Model repository with documentation / Free download from Hugging Face, Apache 2.0 license | QAT preserves near-bfloat16 quality while dramatically reducing memory requirements for local inference |
|---|
| GitHub - Luce-Org/lucebox-hub: Lucebox optimization hub: hand-tuned LLM inference, built for specific consumer hardware.github.com | Open Source Software / open source repository / open source | Megakernel achieves 1.87 tok/J on RTX 3090 using a single CUDA dispatch for Qwen3.5-0.8B. |
|---|
| RedHatAI/gemma-4-31B-it-speculator.eagle3 · Hugging Facehuggingface.co | AI Model / model repository / open source | Uses EAGLE-3 speculative decoding for Gemma-4-31B-it. |
|---|
A collection of bookmarks filtered by the tag "Speculative Decoding".
Showing 1-16 of 16 bookmarks tagged with "Speculative Decoding"
All Stories
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
High-performance Lemonade alternative for AMD Strix Halo & Radeon — latest MoE models (Ling-3.0-Flash, Qwen 3.8 Flash Next, Ornith 1.5), bleeding-...