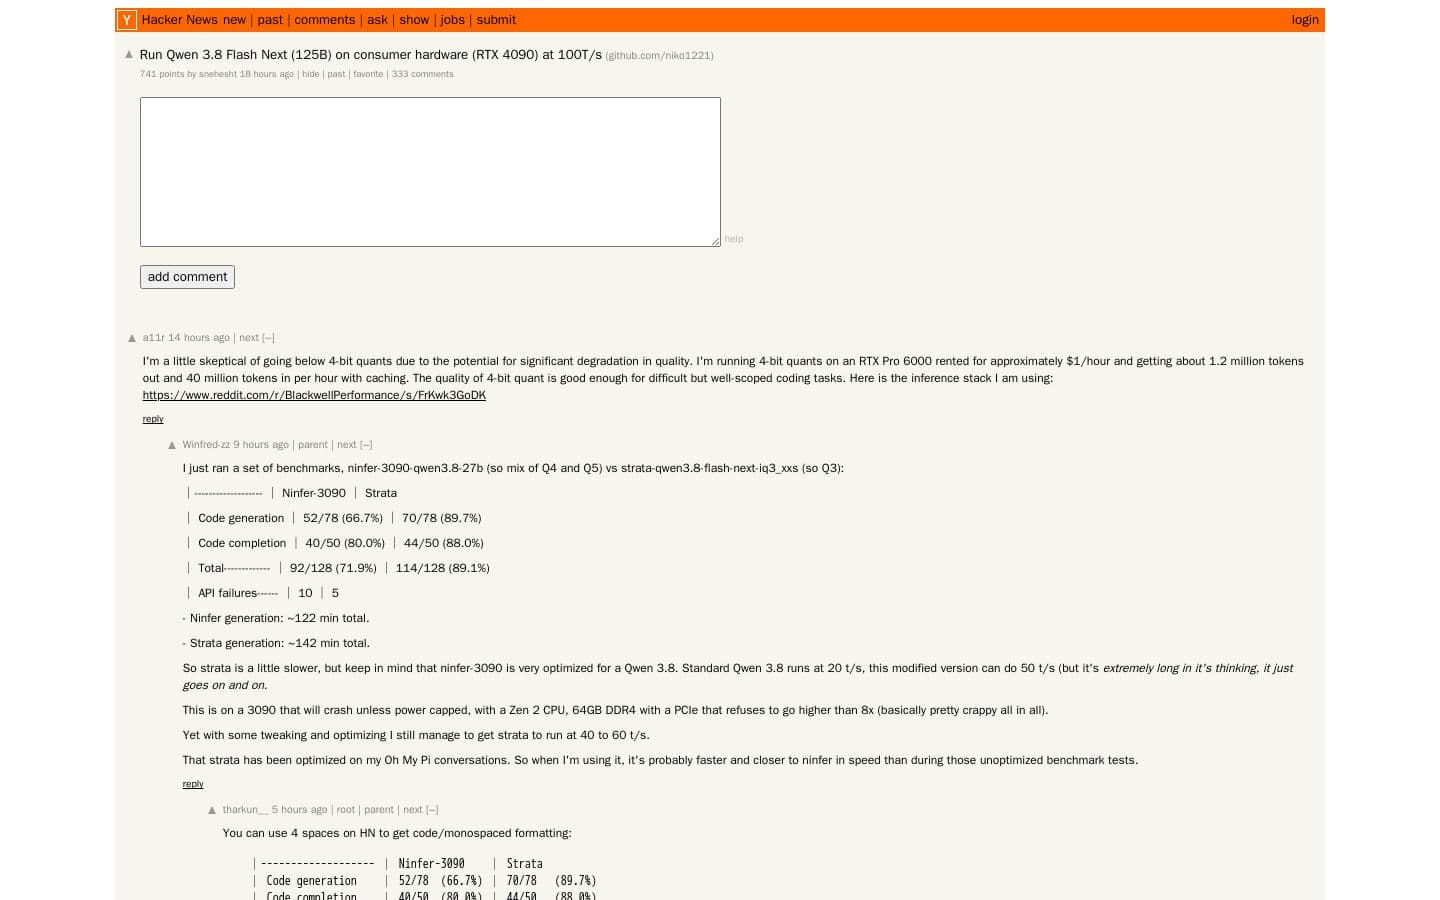
| Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s | Hacker Newsnews.ycombinator.com | LLM Inference Benchmark / Community discussion thread / Free online (Hacker News) | IQ3_XXS quantization scores 89.1% on code tasks vs 71.9% for Q4/Q5 mix, with fewer hallucinations than 27B 4-bit variants |
|---|
| GitHub - Niko1221/Strata: Qwen3.8-Flash-Next (125B MoE) on a 8GB+ NVIDIA GPU: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input.github.com | Local LLM Inference Tool / open-source software project with documentation / free and open source on GitHub | Runs a 125B-parameter MoE model on a single consumer GPU (12-24 GB VRAM) with 64 GB system RAM, eliminating the need for server-grade hardware |
|---|
| hipfire-models/qwen3.8-27b · Hugging Facehuggingface.co | ML Model Repository / model artifact repository / free on Hugging Face (open source) | Complete quantization ladder from 3.5 to 6.6 bits-per-weight with three tiers per bit-width (xt, base, pro) offering a quality/size tradeoff spectrum |
|---|
| GitHub - warpfront/hipfire: RDNA-native LLM inference engine in Rust.github.com | GPU Inference Framework / open-source software project / open source on GitHub; weights on Hugging Face | Rust + HIP with no Python in the hot path; Ollama-style CLI and OpenAI-compatible API on loopback port 11435 |
|---|
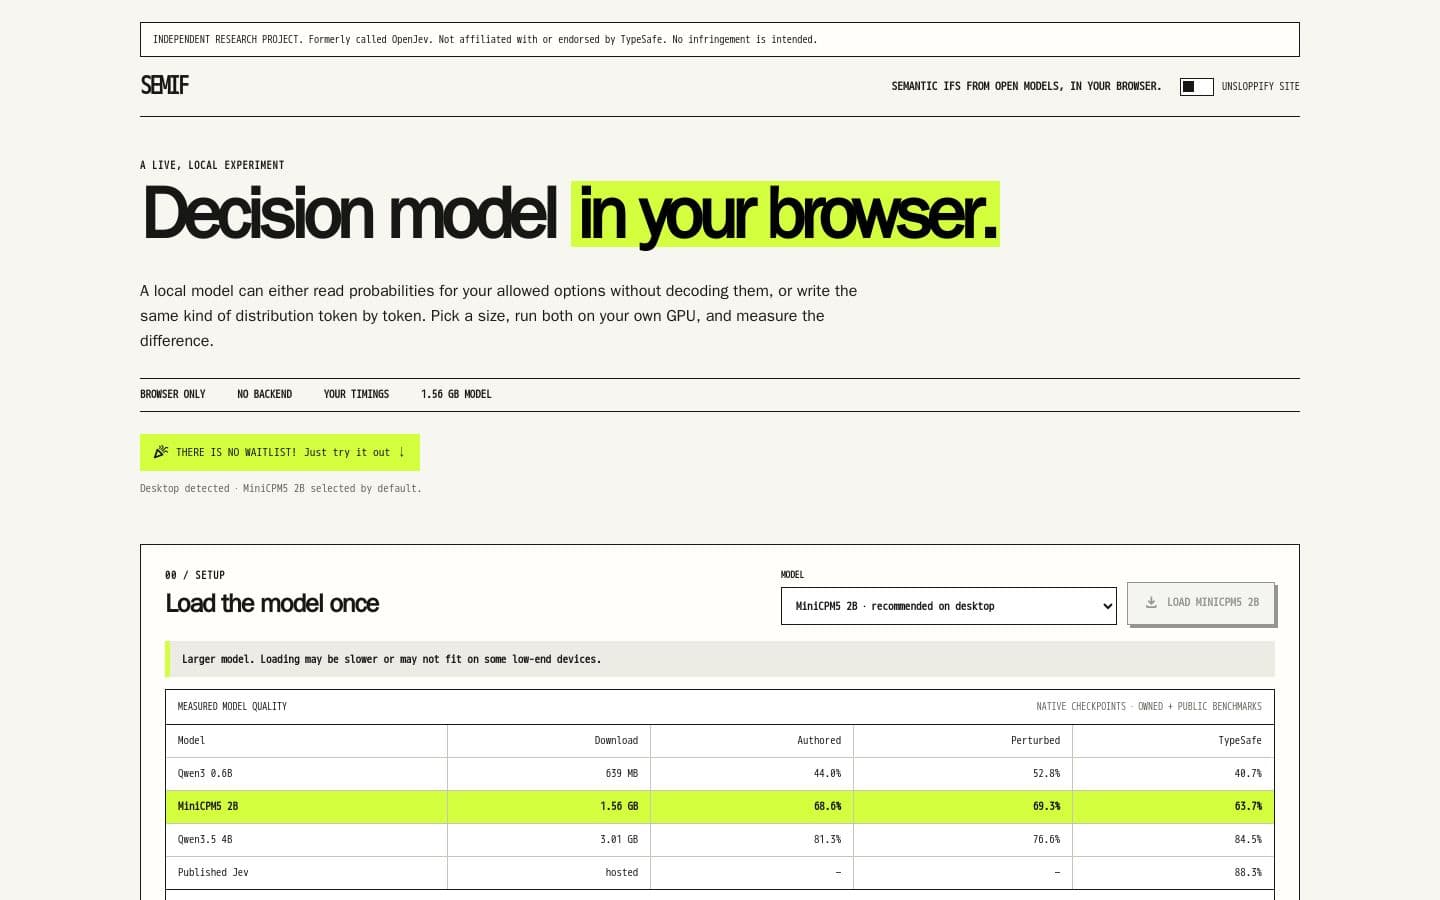
| SemIf — local decisions in your browseropenjev.com | Interactive ML Experiment / interactive web tool / free online, no account required | Runs Qwen3 0.6B, MiniCPM5 2B, and Qwen3.5 4B models entirely in the browser using WebGPU with no backend |
|---|
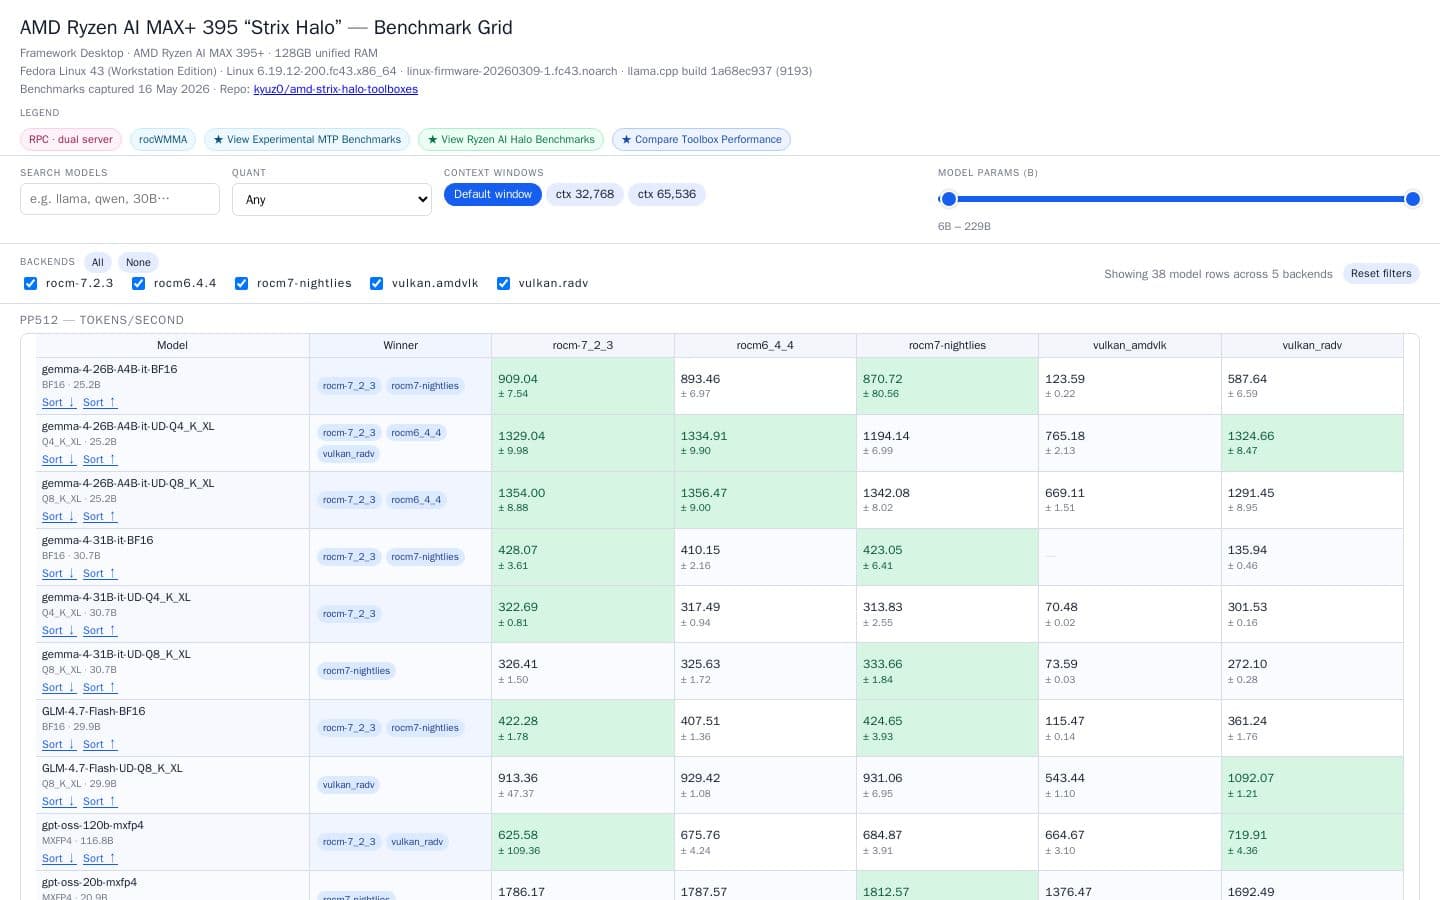
| AMD Strix Halo — Backend Benchmarks (Grid View)kyuz0.github.io | Performance Benchmarks / interactive benchmark dashboard / free online | Compares throughput (tokens-per-second) across 17 LLM configurations ranging from 6.7B to 228.7B parameters. |
|---|
| EschaLabs/Qwen3.8-27B-Escha-W2 · Hugging Facehuggingface.co | Machine Learning Model / Model weights and deployment instructions / Open source | Uses mixed 2/3-bit quantization to achieve a small 10.15 GB weight footprint |
|---|
| Unsloth Dynamic 3.0 GGUFs | Unsloth Documentationunsloth.ai | LLM Quantization Tool / Documentation / Technical Release / Free online documentation; quants available for download | Post-training quantization (no QAT/QAD) using refined imatrix calibration dataset and per-layer quantization selection |
|---|
| vmlinux/Muse-Glimmer-30B-ROCmFPX-GGUF · Hugging Facehuggingface.co | AI Model Quantization / Model repository with documentation / Free download from Hugging Face Hub | First Muse-Glimmer-30B ROCmFPX repository on Hugging Face at publication time; no other ROCmFPX builds existed for this model |
|---|
| Introducing Muse Glimmer: An Open Agentic Model That Runs on Your Deviceresearch.meta.ai | AI Model Release / long-form article / open source | Optimized for always-on local workflows on Mac or PC with a single consumer GPU |
|---|
| PrismML — Announcing Bonsai 27B: The First 27B-Class Model to Run on a Phoneprismml.com | Quantized LLM / product announcement / open source, Apache 2.0 | First 27B-class model to run on a phone; 1-bit variant (3.9 GB) fits within iPhone 17 Pro's memory budget |
|---|
| Holo3.1 - H Companyhcompany.ai | AI Model Release / Product announcement / technical blog post / Free online (model weights available for download) | Quantized checkpoints (FP8, Q4 GGUF, NVFP4) enable fully local inference on consumer and enterprise hardware with minimal performance loss |
|---|
| PrismML — Introducing 1-bit and Ternary Bonsai Image 4B: Image Generation for Local Devicesprismml.com | AI Model Release / technical announcement / open weights | Enables on-device generation on iPhone 17 Pro Max and Mac M4 Pro. |
|---|
| GitHub - QuinsZouls/llama-cpp-turboquant at llama-nextgithub.com | Open Source Library / software repository / open source | Zero-dependency plain C/C++ implementation ensuring broad compatibility. |
|---|
| GitHub - ubergarm/llama.cpp at ug/port-sweep-benchgithub.com | C/C++ Library / open source code repository / free, open source | Plain C/C++ with zero dependencies, optimized for Apple silicon, x86 (AVX/AVX512/AMX), RISC-V, CUDA, Vulkan, and SYCL backends |
|---|