| Niko1221/Strata: Qwen3.8-Flash-Next on any consumer hardware: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input.github.com | Local LLM Inference Engine / open-source software project with documentation / free, open source, self-hosted | One-click desktop app or terminal installer for Windows, Linux, and Mac with no account required |
|---|
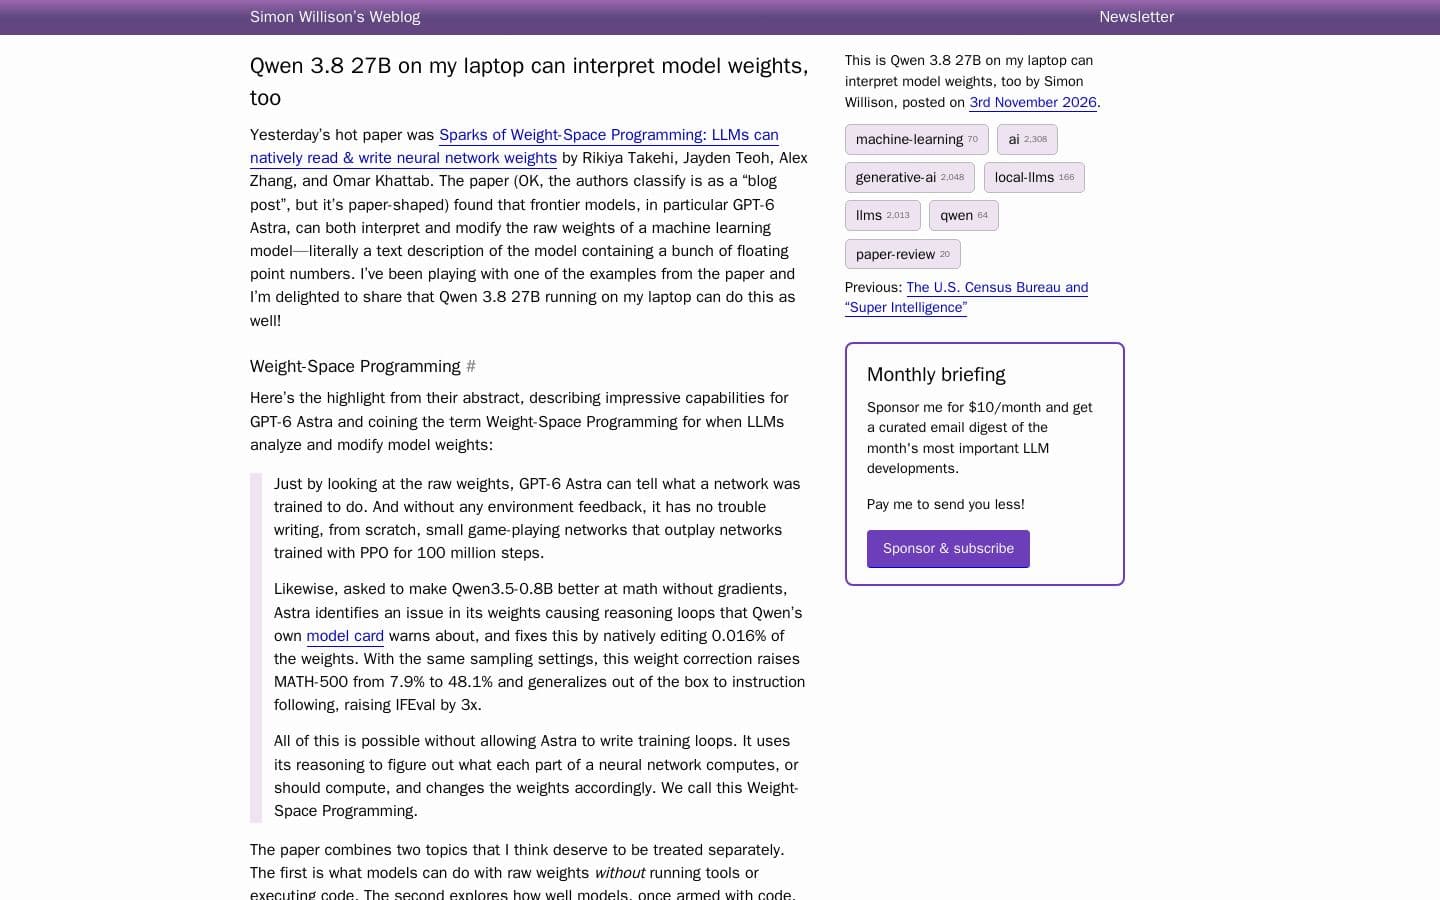
| Qwen 3.8 27B on my laptop can interpret model weights, toosimonwillison.net | AI Research / blog post / free online | Qwen 3.8 27B running locally in LM Studio correctly identified a game from raw weights after 46 minutes and 43,506 reasoning tokens |
|---|
| GitHub - NVIDIA/flare-local-inferencegithub.com | ML Inference Runtime / open-source software repository / open source on GitHub | Two-phase design: Ignition compiles models via PyTorch and CUDA graphs; Helios serves them from a Python-free Rust runtime |
|---|
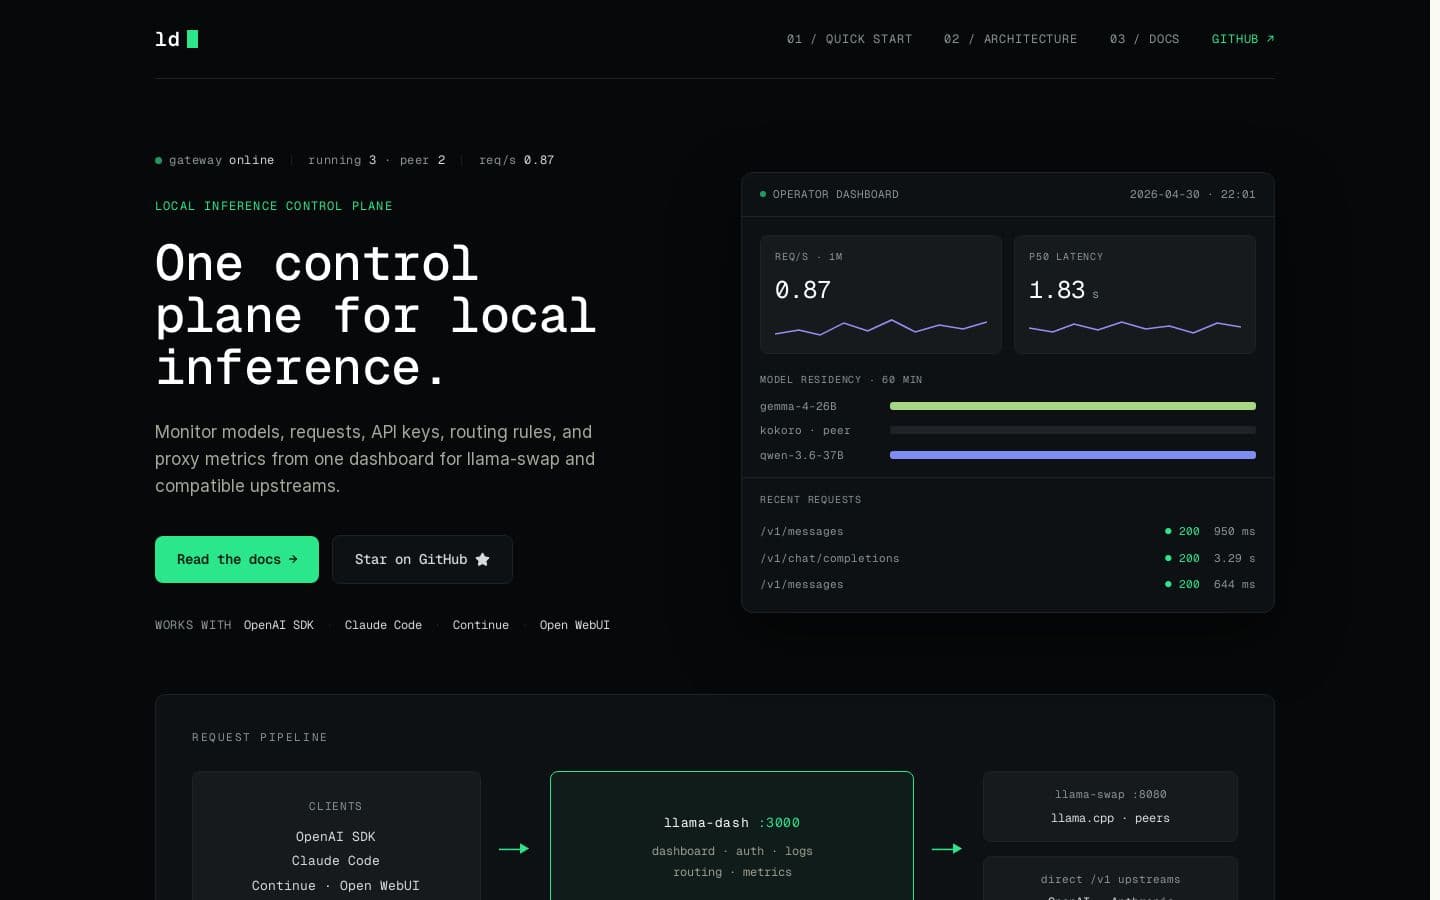
| llama-dash — self-hosted inference gatewayllama-dash.dev | Self-Hosted Inference Tool / self-hosted web dashboard / open source, self-hosted | Unified control plane for local inference with live request, token, model, upstream, and GPU status monitoring |
|---|
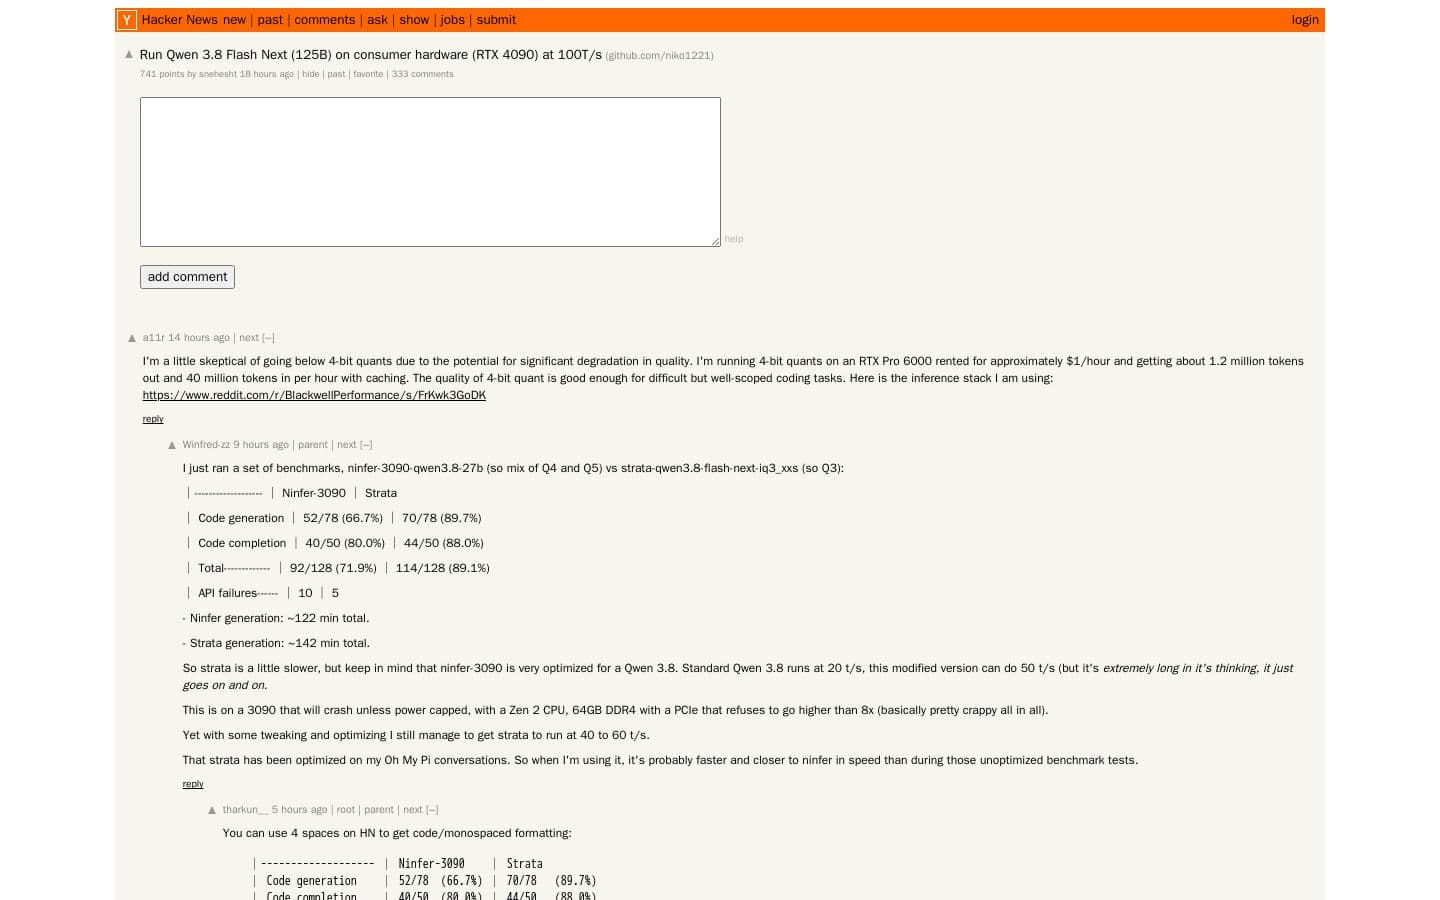
| Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s | Hacker Newsnews.ycombinator.com | LLM Inference Benchmark / Community discussion thread / Free online (Hacker News) | IQ3_XXS quantization scores 89.1% on code tasks vs 71.9% for Q4/Q5 mix, with fewer hallucinations than 27B 4-bit variants |
|---|
| GitHub - Niko1221/Strata: Qwen3.8-Flash-Next (125B MoE) on a 8GB+ NVIDIA GPU: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input.github.com | Local LLM Inference Tool / open-source software project with documentation / free and open source on GitHub | Runs a 125B-parameter MoE model on a single consumer GPU (12-24 GB VRAM) with 64 GB system RAM, eliminating the need for server-grade hardware |
|---|
| DwarfStar 4 (ds4): Local DeepSeek V4.1, Qwen and GLMdwarfstar.sh | Local LLM Inference Engine / project documentation and website / open source, MIT license | Asymmetric 2-bit quantization compresses routed MoE experts while preserving critical shared paths for accuracy |
|---|
| GitHub - gufo-org/gufo: Strix Halo inference engine. Qwen Flash Next Q4_K_XL: 1,628.52pp, 59.41tg single user, 157.22 tok/s 8 users; Qwen27B Q4_K_XL: 656.33pp, 70.56tg tok/s single user with DFlash2github.com | Local AI Inference Engine / open-source software project with documentation and benchmarks / open source on GitHub | Purpose-built for AMD Strix Halo (Ryzen AI MAX+ 395, Radeon 8060S, gfx1151) with up to 128 GiB unified memory |
|---|
| GitHub - claudejaune/Qwen3.8-Halogen-Flash-Strix-Halo: Run Qwen3.8-Flash-Next (180B, 6B active) on a single AMD Strix Halo via the halogen-flash-server containergithub.com | Local LLM Inference Setup / GitHub repository with guided shell scripts / Open source, free; requires AMD Strix Halo hardware with 128 GB RAM | Runs a 180B-parameter MoE model (6B active) on a single AMD Strix Halo with 128 GB RAM — no GPU cluster needed |
|---|
| GitHub - julianmb/halofpx: High-performance Lemonade alternative for AMD Strix Halo & Radeon — latest MoE models (Ling-3.0-Flash, Qwen 3.8 Flash Next, Ornith 1.5), bleeding-edge RDNA 3.5 Wave64/ROCmFP4 kernels, and silicon-tuned profiles.github.com | LLM Inference Server / Open-source software project / Open source on GitHub | Custom Mesa RADV Wave64 cooperative matrix kernels and ROCmFP4 quantization deliver +13.5% decode speed and -16.7% model size vs standard GGUF |
|---|
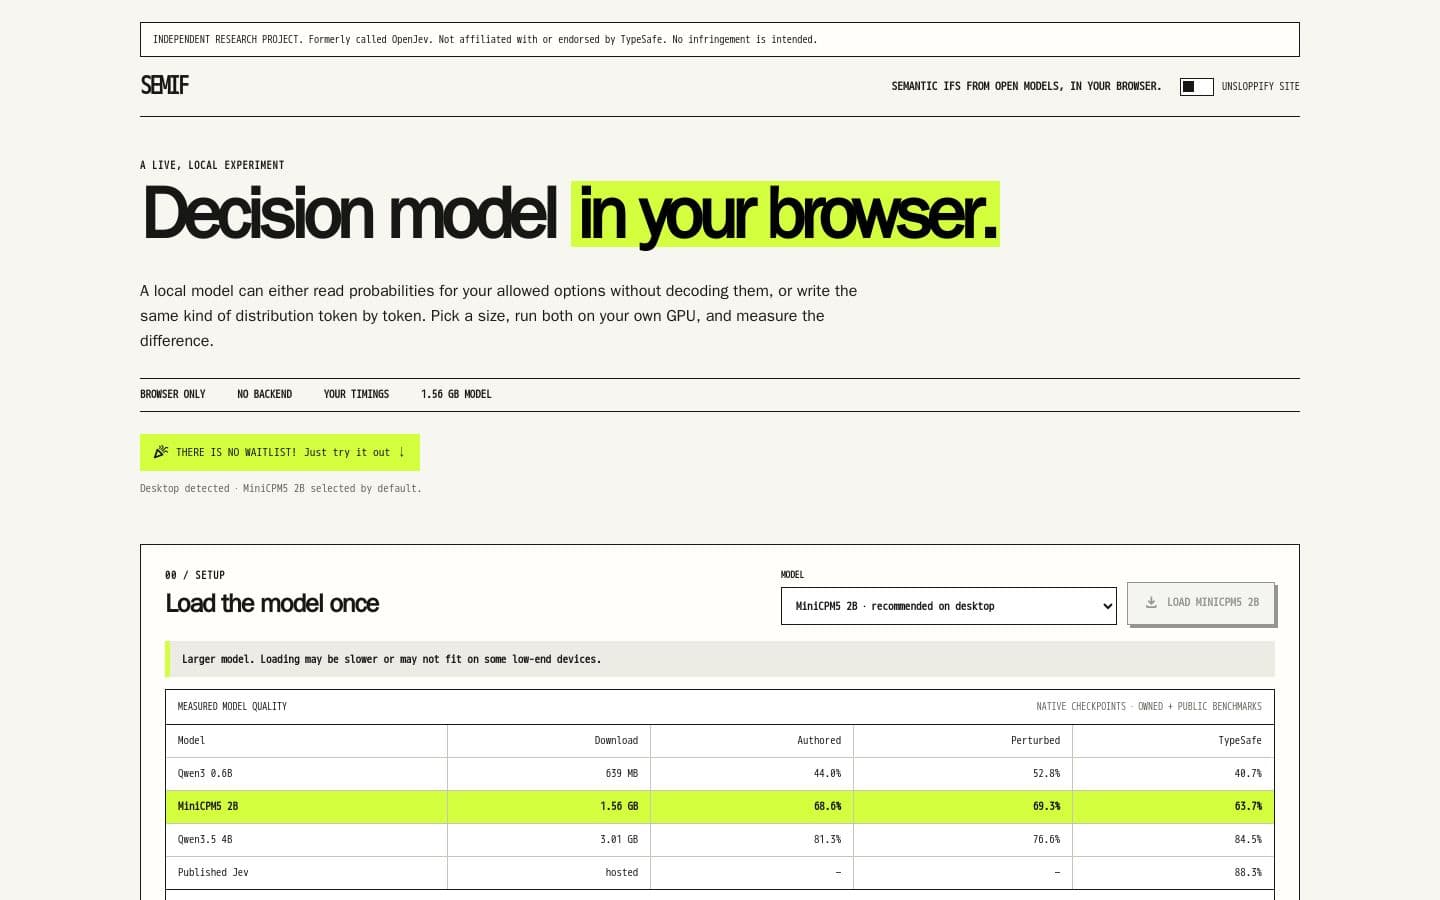
| SemIf — local decisions in your browseropenjev.com | Interactive ML Experiment / interactive web tool / free online, no account required | Runs Qwen3 0.6B, MiniCPM5 2B, and Qwen3.5 4B models entirely in the browser using WebGPU with no backend |
|---|
| GitHub - OnlyTerp/opengrok: Run any model in Grok Bot — one-command setup, model picker UI, evidence-based provider wire maps, and an update-proof doctor. Not farming you, arming you.github.com | Developer Tool / open-source CLI tool with UI / open source on GitHub | One-command setup detects Grok Bot install, adopts existing bindings, and opens a model picker UI |
|---|
| GitHub - FlashML-org/FreeTokengithub.com | Machine Learning Software / open source software / open source | Enables running 290B+ parameter MoE models locally on consumer GPUs (NVIDIA RTX 30, 40, and 50 series). |
|---|
| EschaLabs/Qwen3.8-27B-Escha-W2 · Hugging Facehuggingface.co | Machine Learning Model / Model weights and deployment instructions / Open source | Uses mixed 2/3-bit quantization to achieve a small 10.15 GB weight footprint |
|---|
| GitHub - julianmb/q38rocm: Qwen 3.8 27B ROCmFP4 on AMD Strix Halo (Ryzen AI Max+ 395). Up to 36 tok/s via MTP Speculation, TurboQuant & Mesa RADV Wave64.github.com | Machine Learning Deployment / Open source software repository / Open source | Achieves high throughput of up to 36 tokens per second |
|---|