Unsloth Dynamic 3.0 GGUFs | Unsloth Documentation
Unsloth Dynamic 3.0 GGUFs are post-training quantizations (no QAT/QAD) using a refined imatrix calibration dataset and per-layer quantization selectio...
This curated guide brings together 12 vetted LLM Fine-Tuning resources, including 9 with structured technical analysis and 0 with practitioner field notes. Primary focus areas include AI Development Toolkit, AI/ML Tutorial, LLM Fine-Tuning Guide, LLM Fine-Tuning Project, Local AI Training Tool. Primary sources include github.com, unsloth.ai, blogs.nvidia.com, docs.unsloth.ai, m.youtube.com.
| Resource | Category & Format | Key Takeaway & Notes |
|---|
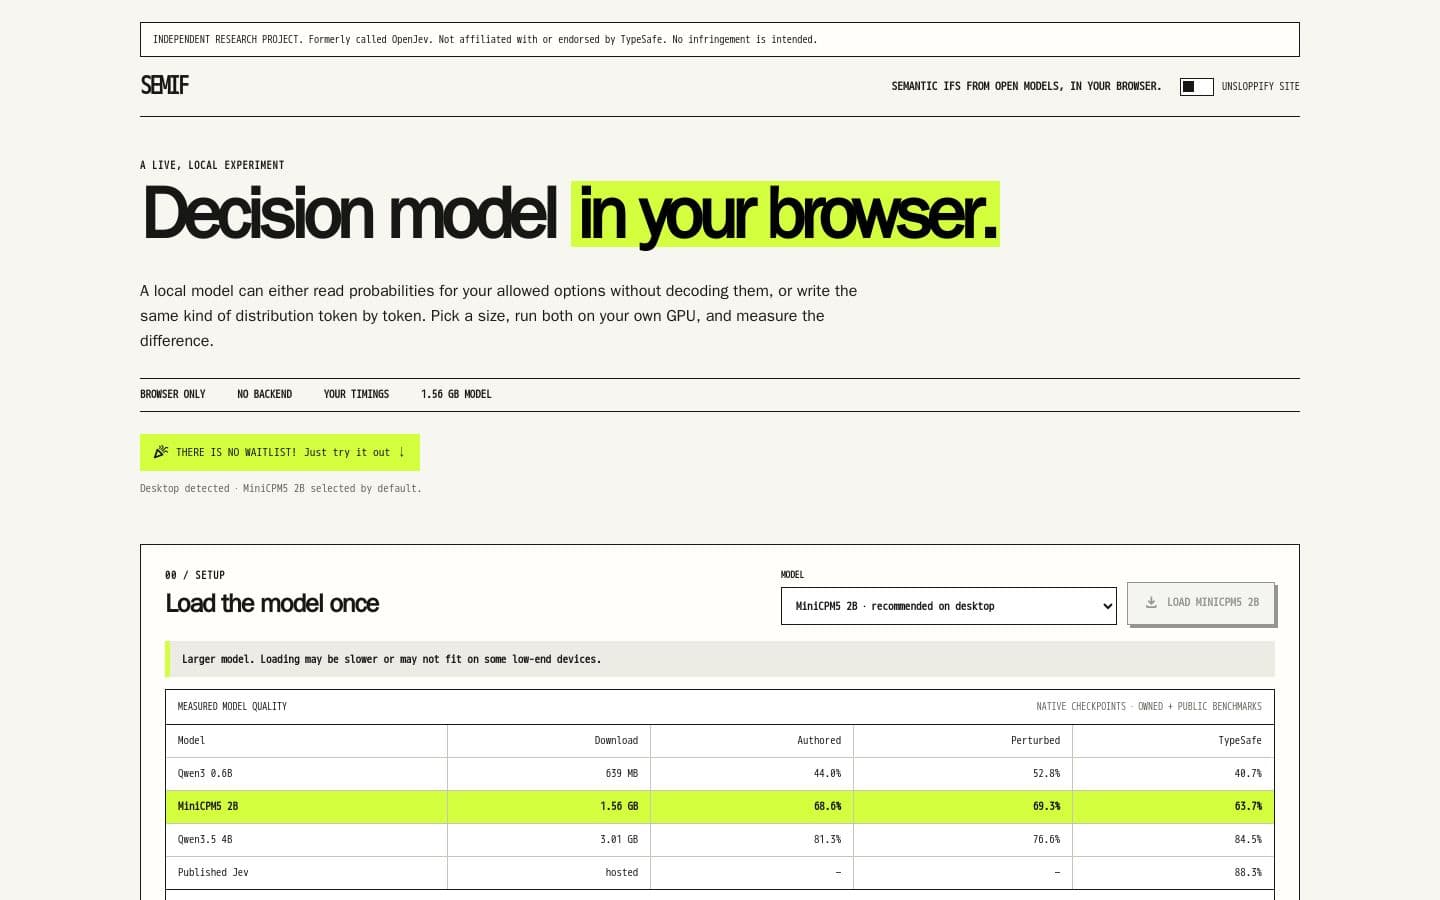
| Train your own Decision Model with Unsloth | Unsloth Documentationunsloth.ai | LLM Fine-Tuning Guide / technical documentation / free online documentation with free Colab/Kaggle notebooks | LoRA fine-tuning (r=16, 1-2 epochs) raises downstream accuracy from 30-37% chance level to 77-81% across models of 2.5-14.4GB |
|---|---|---|
| thinking-machines-lab/tinker-cookbook: Post-training with Tinkergithub.com | Python Library / open-source library with documentation and interactive notebooks / open source on GitHub; requires Tinker API key for training access | Offloads distributed training to Thinking Machines Lab infrastructure via a simple API, abstracting away cluster management |
| GitHub - MakazhanAlpamys/Soup: Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.github.com | Python CLI Tool / open source CLI tool / open source, pip install | Layer streaming keeps frozen base weights out of VRAM, feeding one decoder layer at a time — trains Llama-3.1-8B at 3.32 GB peak on a 4 GB RTX 3050 |
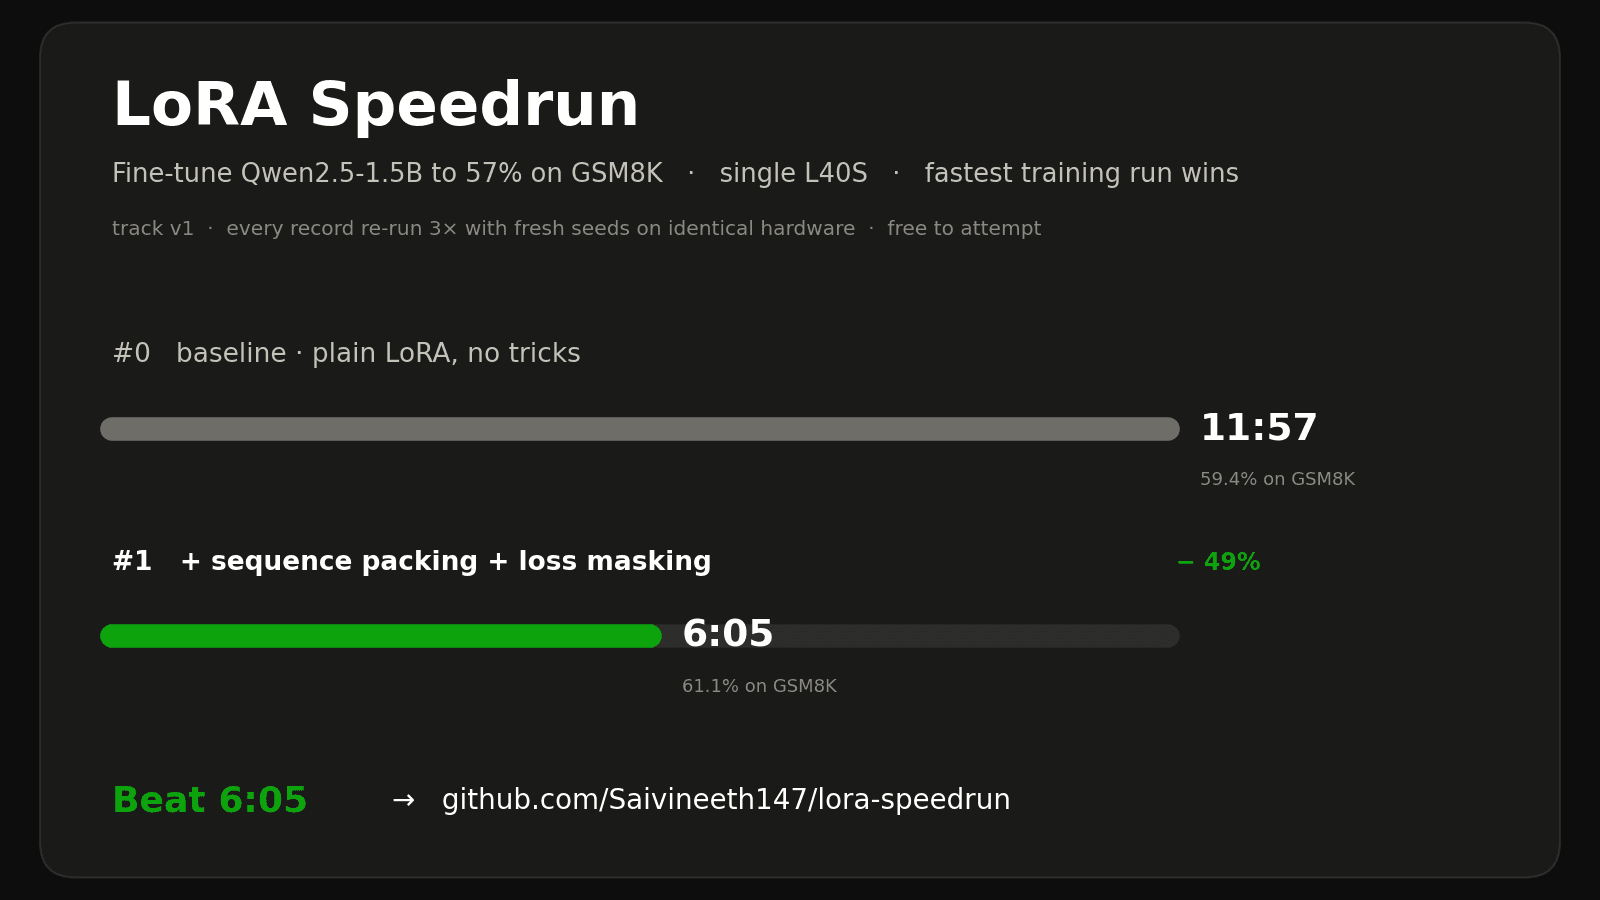
| GitHub - Saivineeth147/lora-speedrun: Speedrunning LoRA fine-tuning: frozen task, frozen hardware, public wall-clock leaderboard. modded-nanogpt for fine-tuning.github.com | ML Benchmarking Project / open-source benchmarking repository with public leaderboard / free online, open source, free compute via Modal credits | Frozen task and hardware: Qwen2.5-1.5B base model, GSM8K train split, single L40S, ≤30M PEFT adapter params |
| fw-ai/cookbook: Recipes and resources for building, deploying, and fine-tuning generative AI with Fireworks.github.com | AI Development Toolkit / open source repository / open source | Provides ready-to-run training recipes for RL (GRPO, DAPO), preference optimization (DPO, ORPO), and supervised fine-tuning (SFT) |
| Fine Tuning a Local LLM to Categorize Questionsteachmecoolstuff.com | LLM Fine-Tuning Project / long-form technical blog post / free online | A 0.6B parameter Qwen model fine-tuned with Unsloth/QLoRA on ~850 labeled entries serves as a lightweight question classifier for a household RAG chatbot |
| Unsloth Studiounsloth.ai | Local AI Training Tool / Product launch announcement with documentation / Open source, free, self-hosted locally | No-code web UI for running, training, and exporting GGUF and safetensor models locally on Mac, Windows, and Linux |
| NVIDIA Nemotron-3-Super: How To Run Guide | Unsloth Documentationunsloth.ai | Technical Documentation / technical guide / free online | Supports local inference on devices with 64GB RAM/VRAM and fine-tuning via Unsloth. |
| How to Fine-Tune an LLM on NVIDIA GPUs With Unslothblogs.nvidia.com | AI/ML Tutorial / technical blog post / free online | Unsloth provides GPU-optimized, low-memory training kernels for Hugging Face Transformer workloads across NVIDIA hardware |
| Fine-Tune Qwen3.8 27B on Your Own Dataset Locally: Step-by-Step Tutorialm.youtube.com | Reference | The video walks through fine-tuning the Qwen3.8 27B model on custom datasets using local hardware and LoRA training. It covers data preparation with Docling for PDF and Office… |
| skills/skills/tinker/SKILL.md at main · sundial-org/skillsgithub.com | Reference | Tinker is a training API for fine-tuning large language models from Thinking Machines Lab, supporting supervised fine-tuning, reinforcement learning, LoRA, and vision-language… |
| Unsloth Docs | Unsloth Documentationdocs.unsloth.ai | Reference | Unsloth is an open-source Python framework that enables fast, memory-efficient fine-tuning and reinforcement learning for major LLMs—including Llama, Mistral, Gemma, Qwen, and… |
A collection of bookmarks filtered by the tag "LLM Fine-Tuning".
Showing 1-12 of 12 bookmarks tagged with "LLM Fine-Tuning"
All Stories
Unsloth Dynamic 3.0 GGUFs are post-training quantizations (no QAT/QAD) using a refined imatrix calibration dataset and per-layer quantization selectio...